# Welcome to Anvilogic

What is Anvilogic?

Anvilogic is an AI SOC solution and multi-data platform that enables detection engineers and threat hunters to detect, hunt, and investigate seamlessly across disparate data lakes and SIEMs without the need to centralize data, learn new languages or deploy new sensors.&#x20;

**Anvilogic empowers enterprise SOCs to rapidly mature their detection programs with a dual approach: instantly deployable, curated detections and a powerful low-code builder for crafting correlated custom alerts.** With thousands of expert-built detections ready to deploy in a single click, teams can accelerate threat coverage from day one. Anvilogic’s platform also features automated workflows and AI-driven insights for tuning, triage, maintenance, and critical alert escalation—helping SOCs hunt threats with greater speed and precision. Real-time SOC maturity scoring gives teams continuous visibility into their detection posture, mapped against their most critical threats.


# Onboarding guide

Congratulations and welcome to Anvilogic!

This guide will help you log in, complete the guided onboarding to set threat priorities and integrate a data repository, get data in, and deploy detections.

## Onboarding workflow <a href="#onboarding-workflow" id="onboarding-workflow"></a>

The following flowchart summarizes the tasks you will complete to get started.

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FEnjU5KMfoO3JSz1sgMc3%2F4.png?alt=media&amp;token=8efbcf48-a9c3-4690-989f-03de2e47a2d1" alt=""><figcaption><p>Anvilogic onboarding tasks</p></figcaption></figure>

## Get started <a href="#get-started" id="get-started"></a>

The Anvilogic platform is supported on the highest versions of Google Chrome and Mozilla Firefox.

If you're ready, [Log in and set your password](/get-started/onboarding-guide/log-in-and-set-your-password) to get started with your Anvilogic onboarding.

## Need help? <a href="#need-help" id="need-help"></a>

If you run into any issues, see [Get help](https://docs.anvilogic.com/get-help/get-help) for information about how you can contact us.


# Log in and set your password

Log in for the first time and set your password on the Anvilogic platform.

Your welcome packet email from Anvilogic contains a link to log in to the Anvilogic platform for the first time. You must change your password the first time you log in to the Anvilogic platform.

1. Make sure you are a user with administrator privileges on the Anvilogic platform.
2. Click **Set Password** in the welcome package email. You are directed to set password page.
3. Enter the email address with which you have registered. This email address must match the email address that the welcome email was sent to.
4. Enter a password meeting the password requirements.
5. Re-enter the password for confirmation.
6. Review the Master service agreement and the privacy policy and click on the check box indicating your consent.
7. Click **Submit**.

After you log in, you will see the first screen of the guided onboarding.

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2F9AjYsTUWo2GvI45VOtkY%2Fwelcome%20to%20anvilogic.webp?alt=media&amp;token=0a2ded0c-9dee-49c5-aaef-54a942810fe5" alt=""><figcaption><p>Guided onboarding welcome screen.</p></figcaption></figure>

Click **Let's Start** to begin.


# Define your company's threat profile

After you log in, use the guided onboarding experience to define your company's threat profile.

Use the guided onboarding to define your company's threat profile and make the Anvilogic platform work according to your needs and priorities.

## Benefits of setting threat priorities <a href="#benefits-of-setting-threat-priorities" id="benefits-of-setting-threat-priorities"></a>

Anvilogic provides prioritized content recommendations based on the following factors:

* Your threat priorities
* Market and industry trends
* Your trusted group activity
* Popular search terms
* Activity from organizations similar to you

Gather your organization’s specific threat priorities to help Anvilogic recommend use cases specific to your organization rather than generic recommendations based on external factors.

## What's in a threat profile? <a href="#whats-in-a-threat-profile" id="whats-in-a-threat-profile"></a>

To build your company profile, provide the information listed in the table. This information helps to filter the MITRE techniques most applicable to you, so that the most relevant recommended content is generated.

<table><thead><tr><th width="190">Category</th><th>Description</th></tr></thead><tbody><tr><td>Region</td><td>Select the geographical region in which your company operates. If you operate in multiple regions, select <strong>Global</strong>.</td></tr><tr><td>Industry</td><td>Select the industry vertical that best represents your company. You can select more than one industry.</td></tr><tr><td>Infrastructure</td><td>Select the infrastructure used within your organization. Select as many as apply to your organization.</td></tr></tbody></table>

## Revisit your threat priorities <a href="#revisit-your-threat-priorities" id="revisit-your-threat-priorities"></a>

As your organization matures over time, you can revisit and update your threat profile to accommodate changes to your infrastructure, including platforms, threat groups, techniques, and data categories.

## Next step <a href="#next-step" id="next-step"></a>

After you define your threat profile, [Select your data repository and get data in](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in).


# Select your data repository and get data in

Select the data repository where you store your logs.

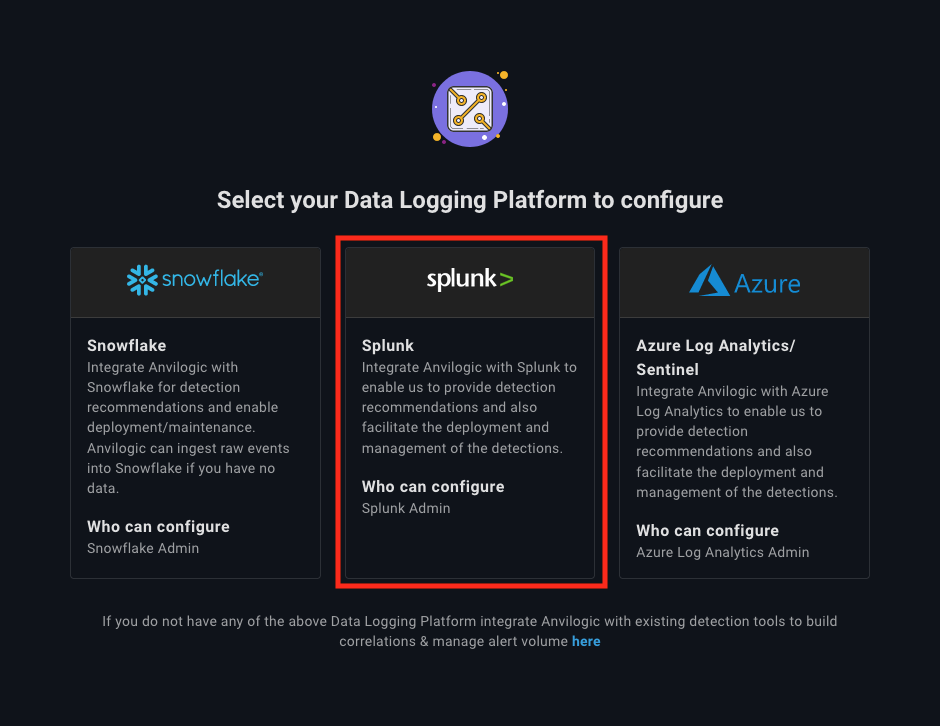
After defining your company profile in the guided onboarding, select a data repository:

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2F9nBAjX7xjclF0SOeux09%2Fonboarding%20-%20data%20repositories.png?alt=media&amp;token=3508a79d-513d-4ce1-9ac9-2f894e3257bd" alt=""><figcaption><p>Select a data logging platform</p></figcaption></figure>

## Next step

Follow the instructions for your data repository.

* [Integrate Splunk as your data repository](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository)
* [Integrate Snowflake as your data repository](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-snowflake-as-your-data-repository)


# Integrate Splunk as your data repository

Integrate the Anvilogic platform with your Splunk Enterprise or Splunk Cloud Platform instance.

After defining your company profile in the guided onboarding, select **Splunk** as the data logging platform.

{% hint style="info" %}
You must have admin privileges in Splunk in order to complete the integration.
{% endhint %}

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FDLXHp3zRDhhFCKD17ESM%2Fsplunk%20data%20repo.png?alt=media&amp;token=5c11883b-b7de-4627-a9e3-0e18b0734337" alt=""><figcaption></figcaption></figure>

## Next step

[Download and install the Anvilogic App for Splunk](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk)


# Download and install the Anvilogic App for Splunk

Integrate Splunk with the Anvilogic platform using the Anvilogic App for Splunk.

The Anvilogic App for Splunk provides triage, allow list and suppressions management, and analytics used by the data feed and productivity scores on the maturity score pages.

You can also enable automated threat detection in the Anvilogic App for Splunk, which is required to generate tuning insights and some hunting insights.

Snowflake-only customers can get tuning insights without the Anvilogic App for Splunk.

## I am a Splunk user <a href="#i-am-a-splunk-user" id="i-am-a-splunk-user"></a>

If you are already using Splunk Enterprise or Splunk Cloud Platform, follow the instructions in the documentation to download and install the Anvilogic App for Splunk.

**Next step**

Select one of the following to continue:

* [Splunk Enterprise](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-enterprise)
* [Splunk Cloud Platform](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-cloud-platform)

## I don't have Splunk <a href="#i-dont-have-splunk" id="i-dont-have-splunk"></a>

If you don't have Splunk, and you want the capabilities provided by the Anvilogic App for Splunk, Anvilogic will provision a Splunk instance for you and manage the installation and upgrade of the Anvilogic App for Splunk.

**Next step**

After the Anvilogic platform is connected to a hosted Splunk instance, [Review data feeds](/get-started/onboarding-guide/review-data-feeds).

<br>


# Splunk Cloud Platform

High-level steps for downloading and install the Anvilogic App for Splunk on Splunk Cloud Platform.

Perform the following tasks to download and install the Anvilogic App for Splunk on Splunk Cloud Platform:

1. [Verify requirements](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-cloud-platform/verify-requirements)
2. [Install the Anvilogic App for Splunk](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-cloud-platform/install-the-anvilogic-app-for-splunk)

## Next step

[Verify requirements](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-cloud-platform/verify-requirements)


# Verify requirements

Verify the requirements on this page before you download and install the Anvilogic App for Splunk.

## Supported versions <a href="#supported-versions" id="supported-versions"></a>

You can integrate the Anvilogic platform with Splunk Cloud Platform versions 8.0.x and higher. Splunk Enterprise Security (ES) versions: 5.0 - 7.0.x are supported.

If you are using the Splunk Cloud Platform Classic experience, you won't be able to accept tuning insights.

See [Splunk Cloud Platform Service Details](https://docs.splunk.com/Documentation/SplunkCloud/latest/Service/SplunkCloudservice) for more information about the differences between Splunk Cloud Platform Classic Experience and Splunk Cloud Platform Victoria Experience.

## Allow IPs <a href="#allow-ips" id="allow-ips"></a>

If you are installing the Anvilogic App for Splunk on Splunk Enterprise Security (ES) search heads in Splunk Cloud Platform, and you also have search heads that are not on Splunk ES, you must allow all IPs to send to the Splunk Cloud HTTP event collector (HEC) endpoint on port 443 since Splunk Cloud Platform does not assign static IPs to the Splunk Cloud Platform search heads.

This setting requires an HEC token for authentication and is often used to send data to Splunk Cloud Platform from multiple devices with dynamic IPs, such as mobile devices. See [Configure IP allow lists for Splunk Cloud Platform](https://docs.splunk.com/Documentation/SplunkCloud/8.2.2105/Admin/ConfigureIPAllowList) in the Splunk Cloud Platform *Admin Config Service Manual* for instructions.

## Remove the app from dual environments <a href="#remove-the-app-from-dual-environments" id="remove-the-app-from-dual-environments"></a>

If your environment includes Splunk ES running on Splunk Cloud Platform Victoria and Splunk Enterprise, the Anvilogic App for Splunk is installed in both environments. You must submit a support ticket with Splunk Support to remove the Anvilogic App for Splunk from one of those environments.

## Next step

After verifying the requirements, [Install the Anvilogic App for Splunk](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-cloud-platform/install-the-anvilogic-app-for-splunk).


# Install the Anvilogic App for Splunk

The process to get the Anvilgic App for Splunk differs depending on whether you are using Splunk Cloud Platform Classic Experience or Splunk Cloud Platform Victoria Experience.

## Splunk Cloud Platform Classic Experience <a href="#splunk-cloud-platform-classic-experience" id="splunk-cloud-platform-classic-experience"></a>

File a service ticket to have Splunk install the Anvilogic App for Splunk for you.

## Splunk Cloud Platform Victoria Experience <a href="#splunk-cloud-platform-victoria-experience" id="splunk-cloud-platform-victoria-experience"></a>

Follow the instructions in [Install a public app from Splunkbase](https://docs.splunk.com/Documentation/SplunkCloud/latest/Admin/SelfServiceAppInstall#Install_a_public_app_from_Splunkbase) in the *Splunk Cloud Pkatform Admin Manual* to install the Anvilogic App for Splunk.

## Next step

[Create the Anvilogic indexes](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/create-the-anvilogic-indexes).


# Splunk Enterprise

High-level steps for downloading and install the Anvilogic App for Splunk on Splunk Cloud Platform.

Perform the following tasks to download and install the Anvilogic App for Splunk on Splunk Enterprise

1. [Verify requirements](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-enterprise/verify-requirements)
2. [Download the Anvilogic App for Splunk](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-enterprise/download-the-anvilogic-app-for-splunk)
3. [Install the Anvilogic App for Splunk](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/download-and-install-the-anvilogic-app-for-splunk/splunk-enterprise/install-the-anvilogic-app-for-splunk)

<br>


# Verify requirements

Verify the requirements on this page before you download and install the Anvilogic App for Splunk.

## Supported versions <a href="#supported-versions" id="supported-versions"></a>

You can integrate the Anvilogic platform with Splunk Enterprise versions 9.0.x and 8.0 - 8.3.x.

Splunk Enterprise Security (ES) versions 5.0 - 7.0.x are supported.

## Where to install the app <a href="#where-to-install-the-app" id="where-to-install-the-app"></a>

Install the Anvilgic App for Splunk on your Splunk search head. The server where you install the Anvilogic App for Splunk must meet the following requirements:

* The server must be able to connect to [https://secure.anvilogic.com](https://secure.anvilogic.com/) over port 443. This is required to download Splunk code and rules metadata.
* The server must be able to connect to [https://eoi-files.anvilogic.com](https://eoi-files.anvilogic.com/) over port 443.
* The server must be able to connect to [https://databus.anvilogic.com](https://databus.anvilogic.com/) over port 443 to send events for third party vendor alert integrations.

If you have multiple Splunk Enterprise instances, install the Anvilogic App for Splunk in only one of those environments.

## Splunk Enterprise deployment considerations <a href="#splunk-enterprise-deployment-considerations" id="splunk-enterprise-deployment-considerations"></a>

For performance considerations, review the following factors in your Splunk Enterprise deployment:

* The number of concurrent users.
* The number of concurrent searches.
* The types of searches used.

See [How concurrent users and and searches impact performance](https://docs.splunk.com/Documentation/Splunk/9.0.1/Capacity/Accommodatemanysimultaneoussearches) in the Splunk Enterprise *Capacity Planning Manual*.

When you deploy threat identifiers on the Anvilogic platform, saved searches are created in your Splunk deployment. You can use cron scheduler recommendations on the Anvilogic platform to manage the load on your Splunk deployment.

## Splunk Enterprise resource and hardware considerations <a href="#splunk-enterprise-resource-and-hardware-considerations" id="splunk-enterprise-resource-and-hardware-considerations"></a>

Resource and hardware considerations for the Anvilogic App for Splunk match the recommendations for your Splunk Enterprise deployment. See [Reference hardware](https://docs.splunk.com/Documentation/Splunk/9.0.1/Capacity/Referencehardware) in the Splunk Enterprise *Capacity Planning Manual*.

Last updated 1 month ago


# Download the Anvilogic App for Splunk

This page provides instructions for downloading the Anvilogic App for Splunk.

## Download instructions <a href="#download-instructions" id="download-instructions"></a>

Perform the following steps to download the Anvilogic App for Splunk:

1. Access [Splunkbase](https://splunkbase.splunk.com/).
2. Click **Login** and log in with your Splunk account.
3. Type **Anvilogic** in the **Search for apps** field. Click on **Anvilogic App for Splunk** in the results.
4. Click **Download**.<br>

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2Fm6Qvg64xyxH4v3XYq2gB%2Fdownload%20the%20app.png?alt=media&amp;token=ad33e5f2-6454-4545-84d4-af3024f31de8" alt=""><figcaption></figcaption></figure>

## Troubleshooting download permissions <a href="#troubleshooting-download-permissions" id="troubleshooting-download-permissions"></a>

If you don't have the permissions to download the app, you will see **Download Restricted** when you try to download the app.

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FlvOqMzY1zHUR67slomD4%2Fdownload%20restricted.png?alt=media&amp;token=5f58b6dc-5399-4ef6-b6ab-01cf2fa32ae3" alt=""><figcaption></figcaption></figure>

If this happens, you must provide Anvilogic with your Splunk.com or Splunkbase username to satisfy Splunk's access control requirements. You must provide this username for each user who requires download access for the Anvilogic App for Splunk.

Perform the following tasks to find your Splunkbase username:

1. Make sure you are logged in to [Splunkbase](https://splunkbase.splunk.com/).
2. Click you user profile photo or avatar, then select **My Profile**.
3. Find your username at the top of the screen, such as **<kevin.hwang@anvilogic.com>** in the following example:

   <figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FQ0SSricJeVKCHK0V98gb%2Fusername.avif?alt=media&amp;token=db663a96-e2ad-4c0a-a9d0-1eedae96bfb8" alt=""><figcaption></figcaption></figure>

## Download the Anvilogic App for Splunk from the Anvilogic platform <a href="#download-the-anvilogic-app-for-splunk-from-the-anvilogic-platform" id="download-the-anvilogic-app-for-splunk-from-the-anvilogic-platform"></a>

If needed, you can download the Anvilogic App for Splunk from the Anvilogic platform:

1. In the Anvilogic platform, click Settings (![](https://kevin-hwang.gitbook.io/~gitbook/image?url=https%3A%2F%2F1880237948-files.gitbook.io%2F%7E%2Ffiles%2Fv0%2Fb%2Fgitbook-x-prod.appspot.com%2Fo%2Fspaces%252FAwYpSzQ2VsCMrVKoFTOY%252Fuploads%252FsaCnEZpsyKIKE8UwMf37%252FSettings%2520Icon.png%3Falt%3Dmedia%26token%3D3b06a619-bd06-4376-bf59-a9b938a7f33d\&width=40\&dpr=4\&quality=100\&sign=d3ef9707\&sv=1)).
2. In the Anvilogic Splunk App field, click **Download**.

The downloaded file is an SPL (Splunk application package) file that can be installed in your Splunk environment.

<br>


# Install the Anvilogic App for Splunk

Install the Anvilogic App for Splunk in your Splunk Enterprise environment.

Follow the instructions in the Splunk documentation to install the Anvilogic App for Splunk in your environment:

* If you have a distributed Splunk Enterprise deployment, use the deployer to install the app on your search heads. See [Install an add-on in a distributed Splunk Enterprise deployment](https://docs.splunk.com/Documentation/AddOns/released/Overview/Distributedinstall) in the *Splunk Supported Add-ons* manual.
* If you have a single-instance Splunk Enterprise deployment, install the app on the search head. See [Install an add-on in a single-instance Splunk Enterprise deployment](https://docs.splunk.com/Documentation/AddOns/released/Overview/Singleserverinstall) in the *Splunk Supported Add-ons* manual.

You must restart Splunk to complete the installation.


# Create the Anvilogic indexes

Create the required custom indexes on the Splunk platform.

The Anvilogic App for Splunk requires custom Splunk indexes used by the HTTP Event Collector (HEC) collector command for auditing, metrics and reporting:

1. Create an index named **\<your-org-name>\_anvilogic** for storing Anvilogic rule output and auditing the app. See [Create events indexes](https://docs.splunk.com/Documentation/Splunk/latest/Indexer/Setupmultipleindexes#Create_events_indexes_2) in the Splunk Enterprise *Managing Indexers and Clusters of Indexers* manual.
2. Create a metrics index named **\<your-org-name>\_anvilogic\_metrics** for storing the output of baselining rules. See [Create metrics indexes](https://docs.splunk.com/Documentation/Splunk/latest/Indexer/Setupmultipleindexes#Create_metrics_indexes) in the Splunk Enterprise *Managing Indexers and Clusters of Indexers* manual.

## Next step

[Assign the avl\_admin role](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/assign-the-avl_admin-role).


# Assign the avl\_admin role

Assign the avl\_admin role to your admin users.

Use Splunk Web to assign the avl\_admin role to app administrators. See [Create and manage roles with Splunk Web](https://docs.splunk.com/Documentation/Splunk/latest/Security/Addandeditroles) in the *Securing Splunk Enterprise* manual for instructions.

{% hint style="info" %}
Assign desired roles directly to each user. Don't inherit user roles through another role.
{% endhint %}

## Customize roles <a href="#customize-roles" id="customize-roles"></a>

The following roles are available on the Anvilogic App for Splunk. See [Summary of roles and privileges](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/overview/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/assign-the-avl_admin-role#summary-of-roles-and-privileges) to see a summary of the privileges provided by each role.

* avl\_admin
* avl\_senior\_developer
* avl\_developer
* avl\_senior\_triage
* avl\_triage
* avl\_readonly

You can customize the avl\_senior\_developer, avl\_developer, avl\_senior\_triage, `and` avl\_triage roles. The avl\_admin and avl\_readonly roles can't be modified.

For example, perform the following tasks to customize the capabilities allowed or restricted by the AVL Senior Developer role:

1. In the Anvilogic App for Splunk, select **Settings > App Configuration**.
2. Click **User Settings** to expand the section.
3. Click **Customize AVL Senior Developer Role** to expand the section for that role.
4. Deselect any capabilities you want to remove for this role, or select a capability to add it to the role.
5. Click **Save**.

## Summary of roles and privileges <a href="#summary-of-roles-and-privileges" id="summary-of-roles-and-privileges"></a>

The following table lists the roles in the Anvilogic App for Splunk and the privileges granted by each role. You can customize the privileges enabled for each role as desired.

<table><thead><tr><th width="297">Privilege</th><th width="114">AVL Senior Developer</th><th width="112">AVL Developer</th><th width="109">AVL Senior Triage</th><th>AVL Triage</th></tr></thead><tbody><tr><td><strong>Allowlist privileges</strong></td><td></td><td></td><td></td><td></td></tr><tr><td><a data-footnote-ref href="#user-content-fn-1">avl_add_al_rule_entry</a></td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td><a data-footnote-ref href="#user-content-fn-2">avl_remove_al_rule_entry</a></td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td><a data-footnote-ref href="#user-content-fn-2">avl_modify_al_rule_entry</a></td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_add_al_global_entry</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_remove_al_global_entry</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_modify_al_global_entry</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_manage_rule_al</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_manage_global_al</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td><strong>Triage privileges</strong></td><td></td><td></td><td></td><td></td></tr><tr><td>avl_change_first_alert_status</td><td></td><td></td><td></td><td>✓</td></tr><tr><td>avl_change_all_alert_status</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_change_alert_status_to_new</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_bulk_alert_status</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_add_observation</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_remove_observation</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_rate_rule</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_add_rule_feedback</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_create_case</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_suppress_alert</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_suppress_global_alert</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td><strong>Content deployment privileges</strong></td><td></td><td></td><td></td><td></td></tr><tr><td>avl_deploy_content</td><td>✓</td><td></td><td></td><td></td></tr><tr><td>avl_write_hec</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_post_rest_platform</td><td>✓</td><td></td><td>✓</td><td></td></tr><tr><td>avl_post_rest</td><td>✓</td><td>✓</td><td>✓</td><td></td></tr><tr><td>avl_get_rest</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_rest_config_access_get</td><td>✓</td><td>✓</td><td>✓</td><td>✓</td></tr><tr><td>avl_rest_config_access_post</td><td></td><td></td><td></td><td></td></tr></tbody></table>

## Next step

[Configure the HEC collector commands](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/configure-the-hec-collector-commands).

[^1]: Add an entry to a rule allow list.

[^2]: Remove an entry in a rule allow list.


# Configure the HEC collector commands

Create a HEC token that can write to the custom indexes you just created.

The Anvilogic App for Splunk contains a custom Splunk command that uses the HTTP Event Collector (HEC) to send results from threat identifiers into the events of interest index. This command is critical to the frameworks ability to store events for advanced correlation, and manages auditing on all objects.

More information on the HEC and how to set it up can be found in [Configure HTTP Event Collector on Splunk Enterprise](https://docs.splunk.com/Documentation/Splunk/8.0.2/Data/UsetheHTTPEventCollector#Configure_HTTP_Event_Collector_on_Splunk_Enterprise) in the Splunk Enterprise *Getting Data In* manual.

Perform the following steps to create inputs on a single search head. Some steps may vary if you are managing a search head cluster.

1. In Splunk Web, select **Settings > Data inputs**.
2. Select **HTTP Event Collector > New Token**.
3. Fill in relevant information:
   * Specify a name of **avl\_hec\_token**.
   * Leave the Source Name Override blank.
   * Enter **HEC Input for Anvilogic Detection Framework** as the description.
   * Leave the Output Group as none.
   * Leave the **Enable indexer acknowledgement** box unchecked.
4. Click **Next** to configure the input settings:
   * Source type = Automatic
   * App Context = Anvilogic (anvilogic)
   * index = anvilogic AND index = anvilogic\_metrics
   * Default Index = anvilogic
5. Click **Review**, then click **Submit**.
6. Copy the token value.

Perform the following steps to update the global settings and enable the tokens:

1. In Splunk Web, select **Settings > Data inputs**.
2. Select **HTTP Event Collector > Global Settings**.
3. Ensure the following settings are enabled:
   * All Tokens: Enabled
   * Enable SSL - Check
   * HTTP Port Number = Default is 8088

## Next step

[Connect to the Anvilogic platform](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-splunk-as-your-data-repository/connect-to-the-anvilogic-platform).


# Connect to the Anvilogic platform

After you install the Anvilogic App for Splunk, you must configure the app to connect to the Anvilogic platform.

## Connect the app to the Anvilogic platform <a href="#connect-the-app-to-the-anvilogic-platform" id="connect-the-app-to-the-anvilogic-platform"></a>

Perform the following steps to complete your initial configurationand connect the Anvilogic App for Splunk to the Anvilogic platform:

{% hint style="info" %}
You must have the avl\_admin role to edit the app configuration page.
{% endhint %}

1. In Splunk Web, select **Apps > Anvilogic** to access the Anvilogic App for Splunk.
2. If this is your first time installing the Anvilogic App for Splunk, you are prompted to set up the app. Click **Continue to app setup page**. To access the app configuration settings after the initial configuration, go to **Settings > App Configuration**.
3. Complete the general settings.
   1. On the Anvilogic platform, select **Settings > Generate API Ke**y. Copy the generated API key.
   2. Navigate to the Anvilogic App for Splunk.
   3. Select **Setting > App Configuration**.
   4. Click and expand the **General Settings** section.
   5. Click and expand the **API Settings** section.
   6. Paste the API key you copied earlier into the **API Key** field.
4. If your network requires a proxy to connect to Anvilogic, configure the proxy settings in the Anvilogic App for Splunk configuration page.
5. Click **Save**.

## Verify the connection <a href="#verify-the-connection" id="verify-the-connection"></a>

In your Splunk instance, run the following Splunk search to verify your app's connection with the Anvilogic platform:

```splunk-spl
| avlmanage command=check_app_health
```

You can view your connection status along with other system health information in the Health Monitoring dashboard in the Anvilogic App for Splunk.&#x20;

## Next step

[Review data feeds](/get-started/onboarding-guide/review-data-feeds).


# Integrate Snowflake as your data repository

Integrate the Anvilogic platform with Snowflake.

## Choose Snowflake <a href="#choose-snowflake" id="choose-snowflake"></a>

After defining your company profile in the guided onboarding, select **Snowflake** as the data logging platform.

You must have admin privileges in Snowflake in order to complete the integration.

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FtFoOLzOhhYRzm8sXFt9k%2Fsnowflake%20data%20repo.png?alt=media&amp;token=eade6554-1bb1-4309-9221-164b2450c74e" alt=""><figcaption></figcaption></figure>

## Connect Snowflake to the Anvilogic platform <a href="#connect-snowflake-to-the-anvilogic-platform" id="connect-snowflake-to-the-anvilogic-platform"></a>

Perform the following steps to complete the integration with Snowflake:

1. Input your Snowflake account identifier to establish a connection between your Snowflake instance and the Anvilogic platform.
2. Click **Copy Code**, then click **Go to Snowflake** to go to your Snowflake instance and run the copied SQL commands. This set of SQL commands creates the necessary Snowflake components, the anvilogic\_service Snowflake user used by the Anvilogic platform, and assigns the necessary permissions to the anvilogic\_admin role for the anvilogic\_service user.
3. Perform the following tasks in your Snowflake instance:
   1. Open a new worksheet.
   2. Change the role from PUBLIC to ACCOUNTADMIN.
   3. Paste the copied SQL commands into the new worksheet.
   4. Click the **All Queries** checkbox to run all the commands.
   5. Click **Run**.
   6. Look for the **Statement executed successfully** message.

      <figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2F6JzCn88VHTCnLXdfIwBn%2Fsnowflake%20config%201.png?alt=media&amp;token=6c71eaec-b4ce-4909-9a6f-c1223b0d6a6d" alt=""><figcaption></figcaption></figure>
4. Return to the Anvilogic platform, then click **Next**.
5. Click **Copy Code**, then click **Go to Snowflake** to go to your Snowflake instance and run the copied SQL commands. This set of SQL commands creates the S3 storage integration and allows access to the anvilogic\_service user so that a connection to your managed S3 bucket where Snowflake retrieves the data can be made.
6. Perform the following tasks in your Snowflake instance:
   1. Open a new worksheet.
   2. Change the role from PUBLIC to ACCOUNTADMIN.
   3. Paste the copied SQL commands into the new worksheet.
   4. Click the **All Queries** checkbox to run all the commands.
   5. Click **Run**.
   6. Look for the **Statement executed successfully** message.

      <figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FMusHnmxr234F0uGmJCW4%2Fsnowflake%20config%202.png?alt=media&amp;token=91a80596-c7cc-4c8b-a230-adb5f4a83c5d" alt=""><figcaption></figcaption></figure>
7. Return to the Anvilogic platform, then click **Add**.

## Next step <a href="#next-step" id="next-step"></a>

After you have defined your company's threat profile and connected Snowflake as a data repository, it's time to [Get data into Snowflake](/get-started/onboarding-guide/select-your-data-repository-and-get-data-in/integrate-snowflake-as-your-data-repository/get-data-into-snowflake).


# Get data into Snowflake

Get your data into Snowflake, where it can be used to generate detections on the Anvilogic platform.

## Assumptions <a href="#assumptions" id="assumptions"></a>

This document assumes you have completed the guided onboarding:

* You have defined your company threat profile.
* You have integrated Snowflake as your data repository

Before you continue, make sure you are a user with administrator privileges on the Anvilogic platform.

## Data onboarding summary <a href="#data-onboarding-summary" id="data-onboarding-summary"></a>

The following flowchart summarizes the process for getting your data into Snowflake.

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2Fy8EXK9OISCwf94FWVv4L%2Fsnowflake%20workflow.webp?alt=media&amp;token=28749165-9e39-492c-aa1a-d0017487ebc7" alt=""><figcaption></figcaption></figure>

## Data onboarding steps <a href="#next-steps" id="next-steps"></a>

Pick one of the following next steps, depending on your infrastructure:

### Self-managed pipelines

Before you begin, make sure you read [Best practices for Snowflake](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/best-practices-for-snowflake). This document contains important information for optimizing your data onboarding for the best performance.

After you review the best practices, see [Snowflake data ingestion](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/integrations/snowflake-data-ingestion) for supported data sources and onboarding instructions for each data source.

### Anvilogic-managed pipelines

See [Snowflake data ingestion](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/integrations/snowflake-data-ingestion) for a list of supported data sources. Click on the name of a data source and follow the instructions to get the data into Snowflake. Anvilogic manages the pipelines for these data sources once you have the data source integrated.

If you have a data source that is not listed here, use [Snowflake custom data](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/integrations/snowflake-data-ingestion/snowflake-custom-data) to get your data in. [Cribl Stream](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/integrations/snowflake-data-ingestion/snowflake-custom-data/cribl-stream) is the recommended way to get your data sources into Snowflake. If you don't use Cribl Stream, you can use your own pipelines [Forward events](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/integrations/snowflake-data-ingestion/snowflake-custom-data/forward-events) to Snowflake.

## Next step

[Review data feeds](/get-started/onboarding-guide/review-data-feeds)


# Review data feeds

Review the category mappings and quality of your data feeds.

Your data feeds are automatically categorized and synchronized to the Anvilogic platform every 7 days. When you add a data feed, you can view it on the Data Feeds page within 7 days.

## Review the data feed category <a href="#review-the-data-feed-category" id="review-the-data-feed-category"></a>

Verify the category of your data feeds matches what you expect, as this affects your MITRE coverage. Select **Maturity Score** (<img src="https://kevin-hwang.gitbook.io/~gitbook/image?url=https%3A%2F%2F1880237948-files.gitbook.io%2F%7E%2Ffiles%2Fv0%2Fb%2Fgitbook-x-prod.appspot.com%2Fo%2Fspaces%252FAwYpSzQ2VsCMrVKoFTOY%252Fuploads%252F2xT0C6uunpRmXWlno0pM%252FMaturity%2520Score%2520Icon.jpg%3Falt%3Dmedia%26token%3Dce317712-4b5e-4d1e-8483-6db9de20eb34&#x26;width=38&#x26;dpr=4&#x26;quality=100&#x26;sign=923e00e2&#x26;sv=1" alt="" data-size="line">) **> Data Feeds** from the navigation bar, the review the categories for each data feed:

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FtdR5gyS9MiL14Ef1KvAW%2Fdata%20feed%201.avif?alt=media&amp;token=b5673e5c-ffec-425f-a6cd-a93d908af64c" alt=""><figcaption></figcaption></figure>

To change or add categories to a data feed:

1. Click on the name of the data feed.
2. Click **Tags**.
3. In the **Data Categories**, field, enter the data categories you want associated with this data feed.
4. Click **Update** when you are finished.

## Review the data feed quality <a href="#review-the-data-feed-quality" id="review-the-data-feed-quality"></a>

Select **Maturity Score** (![](https://kevin-hwang.gitbook.io/~gitbook/image?url=https%3A%2F%2F1880237948-files.gitbook.io%2F%7E%2Ffiles%2Fv0%2Fb%2Fgitbook-x-prod.appspot.com%2Fo%2Fspaces%252FAwYpSzQ2VsCMrVKoFTOY%252Fuploads%252F2xT0C6uunpRmXWlno0pM%252FMaturity%2520Score%2520Icon.jpg%3Falt%3Dmedia%26token%3Dce317712-4b5e-4d1e-8483-6db9de20eb34\&width=38\&dpr=4\&quality=100\&sign=923e00e2\&sv=1)) **> Data Feeds** from the navigation bar, the review the quality for each data feed:

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FGX5deXbq3TFUiwO3hevq%2Fdata%20feed%202.avif?alt=media&amp;token=e167b7be-9fc7-41bd-9d77-ec3879dbce57" alt=""><figcaption></figcaption></figure>

An initial quality feed assessment is made by the Anvilogic platform for any new data feed added to the Anvilogic platform.

Perform your own evaluation of the timeliness, logging level, field extraction, and monitoring scope for each data feed so you can assign a proper data feed quality. Feed quality is important because only **Good** quality feeds are used to generate recommendations on the Anvilogic platform.

To manually change the quality of a data feed:

1. Click on the name of the data feed.
2. Select one of the qualities from the **Feed Quality** dropdown.
3. Click **Update** when you are finished.

Auto-compute feed qualities are available for Windows event logs in Splunk. See [Data feed quality auto computation](https://kevin-hwang.gitbook.io/welcome-to-anvilogic/anvilogic-platform/maturity-score/contributing-scores/how-is-my-feed-score-affecting-my-maturity-score/data-feed-quality-auto-computation).

## Next step

[Review and deploy recommended content](/get-started/onboarding-guide/review-and-deploy-recommended-content).


# (Optional) Upload your existing detections

Upload your existing detections using a CSV file.

{% hint style="info" %}
This is an optional step and if you choose not to do it now, you can come back and do this later at any point in time.
{% endhint %}

If you have existing detections, you can export them to a CSV file, then import the CSV into Anvilogic. Doing this helps you get an idea of what your MITRE coverage looks like, so you can address and strengthen the areas where you need additional coverage.

The CSV file must have the title, description, and search of the existing detection. See [Import existing rules](https://docs.anvilogic.com/anvilogic-platform/maturity-score/contributing-scores/detection-score/import-existing-rules) for instructions to import the CSV file into Anvilogic. This document also describes how to properly format the CSV file when you create it.

## Next step

[Review and deploy recommended content](/get-started/onboarding-guide/review-and-deploy-recommended-content)


# Review and deploy recommended content

Review and deploy a variety of detections on the Anvilogic platform.

The Anvilogic platform generates recommended content for you to deploy based on your threat priorities and good quality data feeds.&#x20;

## Where can I view recommended content? <a href="#where-can-i-view-recommended-content" id="where-can-i-view-recommended-content"></a>

You can view recommended content on the Home page and in the Armory, which shows you all available detections not yet deployed in your system.

## Deploy recommended content <a href="#deploy-recommended-content" id="deploy-recommended-content"></a>

The table defines additional types of recommended content on the Anvilogic platform and how you can deploy them.

<table><thead><tr><th width="203">Content</th><th>Description</th></tr></thead><tbody><tr><td>Threat identifiers</td><td>Recommended threat identifiers can be viewed on the Home page and in the Armory. See <a href="https://docs.anvilogic.com/anvilogic-platform/detect/threat-identifiers/deploy-recommended-threat-identifiers/deploy-a-recommended-snowflake-threat-identifier">Deploy a recommended Snowflake threat identifier</a> for an example of how to deploy a recommended threat identifier from the Home page.</td></tr><tr><td>Trending topics</td><td>Trending topics are in-product versions of the Forge Threat Detection Report emails sent to existing customers. Trending topics can be found on the Home page and the Armory. See <a href="https://docs.anvilogic.com/anvilogic-platform/detect/trending-topics/deploy-a-trending-topic">Deploy a trending topic</a> for an example of how to deploy all the content in a trending topic.</td></tr><tr><td>Detection packs</td><td>Detection packs are collections of threat identifiers, threat scenarios, and macros that address a specific security issue. Detection packs can be viewed in the Armory. See <a href="https://docs.anvilogic.com/anvilogic-platform/detect/detection-packs/deploy-a-detection-pack">Deploy a detection pack</a> for an example of how to deploy all the content in a detection pack.</td></tr></tbody></table>

### Next steps <a href="#next-steps" id="next-steps"></a>

Perform [Additional tasks](/get-started/onboarding-guide/additional-tasks) to set up user access and authentication.


# Additional tasks

As an admin user, grant additional users access to the Anvilogic platform, or set up more secure authentication settings.

## Create users and assign privileges <a href="#create-users-and-assign-privileges" id="create-users-and-assign-privileges"></a>

See [Add a new user](https://docs.anvilogic.com/anvilogic-platform/settings/manage-users/add-a-new-user) for instructions on how to add users who can access the Anvilogic platform. When you add a new user, you assign them roles which grant certain privileges to the user when they access the platform. See [User roles and privileges (RBAC)](https://docs.anvilogic.com/anvilogic-platform/settings/manage-users/user-roles-and-privileges-rbac) for a full list of platform roles.

## Configure additional authentication settings <a href="#configure-additional-authentication-settings" id="configure-additional-authentication-settings"></a>

You can configure additional authentication settings for access to the Anvilogic platform, such as multi-factor authentication (MFA) or single sign-on (SSO). See [Configure MFA with Duo](https://docs.anvilogic.com/anvilogic-platform/settings/authentication-settings/configure-mfa-with-duo) and [Configure SSO](https://docs.anvilogic.com/anvilogic-platform/settings/authentication-settings/configure-sso) for more information.


# Reference Architectures

The following is Anvilogic's reference architecture to support your environment.

## High Level Architecture

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FUzOXG1nXhOArO0vOZx8b%2FGeneral%20Anvilogic%20Architecture.png?alt=media&amp;token=d9fea524-e361-40cf-a0f6-08a7cb74ea3a" alt=""><figcaption><p>General Platform Architecture - High Level Overview</p></figcaption></figure>

### Anvilogic on Splunk Detailed Architecture

{% content-ref url="/pages/RdQNrHvrip7SxADL05lM" %}
[Anvilogic on Splunk Architecture](/get-started/reference-architectures/anvilogic-on-splunk-architecture)
{% endcontent-ref %}

### Anvilogic on Snowflake Detailed Architecture&#x20;

{% content-ref url="/pages/SK60jIHtLUU47oN3IYzB" %}
[Anvilogic on Snowflake Architecture](/get-started/reference-architectures/anvilogic-on-snowflake-architecture)
{% endcontent-ref %}

### Anvilogic on Azure Detailed Architecture&#x20;

{% content-ref url="/pages/DknTb3c4LXmuDNFIGRJ4" %}
[Anvilogic on Azure](/get-started/reference-architectures/anvilogic-on-azure)
{% endcontent-ref %}

### Hybrid - Anvilogic on Splunk & Snowflake Detailed Architecture&#x20;

{% content-ref url="/pages/WFyYtC6DwY0300KcdTkY" %}
[Hybrid - Anvilogic on Splunk & Snowflake Architecture](/get-started/reference-architectures/hybrid-anvilogic-on-splunk-and-snowflake-architecture)
{% endcontent-ref %}


# Anvilogic on Splunk Architecture

Anvilogic implementation with Splunk (Cloud & Splunk on-premise).

### Architecture Diagram&#x20;

Below is the generic architecture digram for how Anvilogic works on top of Splunk. &#x20;

{% hint style="info" %}
This supports both Splunk Cloud (Classic & Victoria) and Splunk on-premise.
{% endhint %}

**Diagram:**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FrwTxEbX4p9btRa2SCHiU%2FReference%20Architecture%20-%20Type%201%20Splunk.png?alt=media&amp;token=11788aef-2a27-4fab-85a7-87c7243ec216" alt=""><figcaption><p>Anvilogic on Splunk (Cloud and On-Premise)</p></figcaption></figure>

**PDF Download:**

{% file src="/files/1CBOTbjCqFekt3OjLsgG" %}

### Frequently Asked Questions (FAQs)

<details>

<summary>How does Anvilogic get installed for Splunk?</summary>

The Anvilogic App for Splunk gets installed on your Search head (single or clustered). It is approved for Splunk on-premises and Splunk Cloud (both Victoria and Classic).

Detections run as saved searches in the AVL app on cron & results go into the Anvilogic index.

</details>

<details>

<summary>How does the Anvilogic SaaS platform communicate with Splunk?</summary>

All communication (detection use cases deployments) are done over REST API using HTTPS/443 with TLS v1.2+.

</details>

<details>

<summary>Can you help bring raw log data into Splunk for us?</summary>

**No**, Anvilogic does not provide a connector service or forwarding agent to help bring security logs into Splunk. Anvilogic only supports raw data ingestion for Snowflake.

</details>

<details>

<summary>Can you help bring alert data into Splunk for us?</summary>

**Yes**, Avilogic can help retrieve alerts/signals from SaaS security tools (ex. Proofpoint, Wiz, Crowdstrike, etc.) and can ingest those into the Anvilogic index for correlation.

</details>

<details>

<summary>Does Anvilogic require Splunk Enterprise Security (ES)?</summary>

**No**, Anvilogic does not require Splunk ES to operate. However, Anvilogic can integrate with the existing ES framework if required.

Anvilogic does have a native triage capability that can replace certain ES components if required.

</details>

<details>

<summary>What data will Anvilogic have access to?</summary>

The Anvilogic Splunk app should be installed on a search head that has access to security data. This will allow the detection team to build and deploy detections to the search heads that have access to the indexed data.&#x20;

All RBAC controls are still maintained by your existing Splunk admins.

</details>

<details>

<summary>What is the Anvilogic Index?</summary>

Anvilogic Index will store the output from all detections that are running within the Anvilogic Splunk app.&#x20;

This is a fully normalized set of signals that we call “events of interest” that can be used to escalate activity to your SOAR or can be used as a hunting index to create Threat Scenario correlations.

</details>

<details>

<summary>Do you collect the alerts stored in the Anvilogic index?</summary>

**Not by default**. Alerts are stored inside of your Splunk index you specify during the Splunk app setup.&#x20;

The Anvilogic AI-Insights (ex. Hunting, Tuning, Health) package requires a copy of these events to be collected and stored by Anvilogic. If enabled, a copy of those events will be collected into Anvilogic.

</details>

<details>

<summary>Do you provide parsers for un-normalized data?</summary>

**Yes**, Anvilogic does not require any Splunk add on to function. We provide hundreds of out-of-the-box parsers that can be used to normalize your security data inside of Splunk.

</details>

<details>

<summary>Do you integrate with SOAR?</summary>

**Yes**, Anvilogic can integrate with most SOARs via REST API through either a push or a pull method.

</details>

<details>

<summary>Does Anvilogic have a triage capability in Splunk?</summary>

**Yes**, our Anvilogic app for Splunk has built in triage and allowlisting capabilities to make it easy to investigate alerts that are being generated. &#x20;

We can also easily integrate with any downstream SOAR platform you are using. &#x20;

</details>


# Anvilogic on Azure

Anvilogic implementation with Azure (Data Explorer, Log Analytics, and Fabric).

### Architecture Diagram&#x20;

Below is the generic architecture digram for how Anvilogic works on top of Azure. &#x20;

{% hint style="info" %}
This supports both Azure Log Analytics, Azure Data Explorer (ADX), and Fabric workspaces.
{% endhint %}

{% hint style="success" %}
We support querying a Log Analytics Workspace in a different tenant than the Anvilogic Azure Data Explorer Cluster. &#x20;

* In order to execute cross-tenant queries against a Microsoft Azure Log Analytics Workspace, the proper permissions first need to be configured.&#x20;
* This can be done using [Azure Lighthouse](https://azure.microsoft.com/en-us/products/azure-lighthouse#layout-container-uidf657), a **free** service that assists customers in managing multiple Azure tenants.&#x20;
* In this case, it is used to assign role-based access control (RBAC) permissions to grant service principals permissions across tenants.&#x20;

Click [here](/get-started/reference-architectures/anvilogic-on-azure/log-analytics-cross-tenant-search) to learn more.
{% endhint %}

{% hint style="info" %}
Questions around cost?  Review [Azure Costs Estimates](/get-started/reference-architectures/anvilogic-on-azure/azure-costs-estimates).
{% endhint %}

**Diagram:**

<div data-full-width="true"><figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2Fvvvm1mWOBLitSJeXM8Q9%2FFeb%207%20Screenshot%20from%20Benji%20Arnold.png?alt=media&amp;token=669b8c1d-e928-4f52-a6e7-30b0c2f59752" alt=""><figcaption><p>Anvilogic's Integration with Azure ADX, LA, Fabric.</p></figcaption></figure></div>

**PDF Download:**

{% file src="/files/ePAEgNpELpWAHaQeY9db" %}

### Frequently Asked Questions (FAQs) <a href="#azure_faq" id="azure_faq"></a>

<details>

<summary>What gets installed in my Azure environment?</summary>

The following infrastructure will be created in the resource group you create for Anvilogic.  We use an [Azure ARM template](https://learn.microsoft.com/en-us/azure/azure-resource-manager/templates/overview) to deploy the infrastructure.

* User managed identity (gives permissions to access key vault, and ADX tables)&#x20;
* Azure Key Vault&#x20;
* ADX Cluster, database, and tables Azure Container App/environment/jobs/instance&#x20;
* Log analytics workspace for the container app&#x20;
* Azure Container app registry & cache
* Azure Data Explorer Cluster
  * Database and tables will be created in the cluster via API

</details>

<details>

<summary>Does Anvilogic's integration incur any Azure costs?</summary>

**Yes**, there are costs associated with running the Anvilogic Resource Group in Azure, specifically on the Azure Data Explorer hosting cluster.  These costs depend on the compute required to execute detections within your environment. &#x20;

The average costs of running Anvilogic's required infrastructure in Azure range from $6,000-$25,000 per year annually depending on how many detections you will be running.&#x20;

The default size is Standard\_E2ads\_v5 (2vCPUs) instead of Standard\_E8ads\_v5 (Medium 8vCPUs).

**What costs money?**

During the set up process, a VM is created that will manage the Data Explorer Cluster. The **default** size upon our automated installation of that VM is a **Standard\_E8ads\_v5 (Medium 8vCPUs).**

**Calculate Costs:**

* Visit [Azure Pricing Page](https://azure.microsoft.com/en-us/pricing/calculator/?ef_id=_k_CjwKCAiA34S7BhAtEiwACZzv4a4xeiNiZlq_hfjhZM3vLpb8w8c_rpPwf7Ezqm6V3iza21xUGQAlYhoChAwQAvD_BwE_k_\&OCID=AIDcmm5edswduu_SEM__k_CjwKCAiA34S7BhAtEiwACZzv4a4xeiNiZlq_hfjhZM3vLpb8w8c_rpPwf7Ezqm6V3iza21xUGQAlYhoChAwQAvD_BwE_k_\&gad_source=1\&gclid=CjwKCAiA34S7BhAtEiwACZzv4a4xeiNiZlq_hfjhZM3vLpb8w8c_rpPwf7Ezqm6V3iza21xUGQAlYhoChAwQAvD_BwE) -> Type in "azure data explorer" under products
* In the Instance section, type "**E8ads"**&#x20;

Refer to [Azure Costs Estimates](/get-started/reference-architectures/anvilogic-on-azure/azure-costs-estimates) for more details.

</details>

<details>

<summary>What permissions do I need to create/use to install Anvilogic’s Azure integration?</summary>

You will be creating the following: 

1. Create new App registration for Anvilogic&#x20;
2. Create a new secret in the new App that was created in Step 1
3. Create an Anvilogic resource group
4. Go through our integration set up on the Anvilogic Platform

</details>

<details>

<summary>Can you query Data Explorer, Log Analytics, and Fabric?</summary>

**Yes**, Anvilogic supports searching and running detection against any data source inside of an Azure LA, ADX cluster, or Fabric workspace.

You will need to give the Anvilogic app service principal permissions to query any of the ADX, LA clusters, or Fabric workspaces you want Anvilogic searches and detections to use.

For **Microsoft Fabric** you need to create a workspace, leverage an event stream under real time intelligence, and the destination from the event stream **MUST** be a KQL Database. &#x20;

The [cluster command ](https://learn.microsoft.com/en-us/kusto/query/cluster-function?view=microsoft-fabric)will then be able to query the KQL database. &#x20;

Currently, we do not support querying a Log Analytics Workspace in a different tenant than the Anvilogic Azure Data Explorer Cluster. &#x20;

</details>

<details>

<summary>How does the Anvilogic platform query our LA, ADX, or Fabric Clusters?</summary>

We connect into your ADX cluster and then use the Microsoft [cluster command](https://learn.microsoft.com/en-us/kusto/query/cluster-function?view=microsoft-fabric) to initiate a query to any other LA, ADX cluster, or Fabric workspace that our app service principal have access to.

For **Microsoft Fabric** you need to create a workspace, leverage an event stream under real time intelligence, and the destination from the event stream MUST be a KQL Database. &#x20;

The [cluster command ](https://learn.microsoft.com/en-us/kusto/query/cluster-function?view=microsoft-fabric)will then be able to query the KQL database. &#x20;

Currently, we do not support querying a Log Analytics Workspace in a different tenant than the Anvilogic Azure Data Explorer Cluster. &#x20;

</details>

<details>

<summary>What if Azure isn't my primary SIEM and I have a hybrid set up?</summary>

Since Anvilogic supports multiple SIEM/Data Lakes, you can configure all of the events if interest (EOIs) generated from detection queries to also write a copy back to your primary Alert Lake or EOI data store.  That can be located in any of the other support platforms (ex. Splunk, Snowflake). &#x20;

For example - if Splunk is your primary SIEM, then you can configure all of your Azure detection results to also send a copy of the event of interest (EOI) back to the Anvilogoic index in Splunk.  The Anvilogic platform handles all of this EOI routing for you.

</details>

<details>

<summary>Can you help bring <em>alert</em> data into Azure for us?</summary>

**Yes**, Anvilogic can help retrieve alerts/signals from SaaS security tools (ex. Proofpoint, Wiz, Crowdstrike, etc.) and can ingest those into the Anvilogic table in ADX for correlation.

</details>

<details>

<summary>Can you help bring <em>raw data</em> into Azure for us?</summary>

**No**, Anvilogic does not support raw data ingestion into ADX, LA, or Fabric.  Data must already be present in those environments. &#x20;

Anvilogic only supports raw data ingestion for Azure Snowflake.

</details>

<details>

<summary>Do you provide parsers for un-normalized data?</summary>

**Yes**, we provide hundreds of out-of-the-box parsers that can be used to normalize your security data inside of ADX,LA, or Fabric. &#x20;

</details>

<details>

<summary>What is the Anvilogic Alert Table in ADX?</summary>

Anvilogic Alert table in ADX will store the output from all detections that are running within the App container environment. &#x20;

This is a fully normalized set of signals that we call “events of interest” that can be used to escalate activity to your SOAR or can be used as a hunting index to create Threat Scenario correlations.

</details>

<details>

<summary>Do you collect the alerts stored in the Anvilogic Alert Table in ADX?</summary>

Alerts are stored inside of your Azure table in ADX you specify during the setup.&#x20;

The Anvilogic AI-Insights (ex. Hunting, Tuning, Health) package requires a copy of these events to be collected and stored by Anvilogic. If enabled, a copy of those events will be collected into Anvilogic.

</details>

<details>

<summary>Do you integrate with SOAR?</summary>

**Yes**, Anvilogic can integrate with most SOARs via REST API through either a push or a pull method.

</details>


# Azure Costs Estimates

Unified Detect for Azure supports both Azure Log Analytics, Azure Data Explorer (ADX), and Microsoft Fabric.

Installing Anvilogic's UD for Azure creates a new Azure Data Explorer cluster in **your** environment that is used to manage objects to run the Unified Detect framework.

During the set up process, a VM is created that will manage the Data Explorer Cluster.  The default size upon our automated installation of that VM is a **Standard\_E2ads\_v5 (Medium 8vCPUs) in a production cluster with SLA.**  This can be changed at any time if the amount of detections you have running requires more compute resources.&#x20;

{% hint style="warning" %}
Review your billing configurations for ADX pricing tiers that control cluster management to ensure proper scaling expectations and configuration for the Anvilogic service to not get terminated.&#x20;

See [#estimated-cluster-sizes](#estimated-cluster-sizes "mention") and [#cluster-size-costs](#cluster-size-costs "mention").
{% endhint %}

### Estimated cluster sizes

The table below assumes each deployed job run averages 1 minute and every rule deployed has the specified job run frequency. In reality, you could have a mix of how long the jobs take to run and how often they run. The table below is a guideline to be used for estimating capacity, and is based on the [Azure Data Explorers default concurrency](https://learn.microsoft.com/en-us/kusto/concepts/query-limits?view=microsoft-fabric) limits, which is the number of cores multiplied by 10.

3 Concurrency job runs are reserved for adhoc jobs executed from the Azure TI Builder view when creating or editing a threat identifier. The remaining jobs are reserved for deployed rules.

{% hint style="info" %}
Other KQL queries being run outside of Azure UD also contribute towards this search concurrency and can cause throttled jobs if the cluster is operating near full utilization.
{% endhint %}

<table><thead><tr><th width="219">Cluster size</th><th>Azure ADX concurrency limit</th><th>Job run frequency (in minutes)</th><th>Deployed rules limit</th></tr></thead><tbody><tr><td>Standard_E2ads_v5</td><td>20</td><td>5</td><td>80</td></tr><tr><td>Standard_E2ads_v5</td><td>20</td><td>15</td><td>240</td></tr><tr><td>Standard_E2ads_v5</td><td>20</td><td>30</td><td>480</td></tr><tr><td>Standard_E2ads_v5</td><td>20</td><td>60</td><td>960</td></tr><tr><td>Standard_E4ads_v5</td><td>40</td><td>5</td><td>180</td></tr><tr><td>Standard_E4ads_v5</td><td>40</td><td>15</td><td>540</td></tr><tr><td>Standard_E4ads_v5</td><td>40</td><td>30</td><td>1,080</td></tr><tr><td>Standard_E4ads_v5</td><td>40</td><td>60</td><td>2,160</td></tr><tr><td>Standard_E8ads_v5</td><td>80</td><td>5</td><td>380</td></tr><tr><td>Standard_E8ads_v5</td><td>80</td><td>15</td><td>1,140</td></tr><tr><td>Standard_E8ads_v5</td><td>80</td><td>30</td><td>2,280</td></tr><tr><td>Standard_E8ads_v5</td><td>80</td><td>60</td><td>4,560</td></tr><tr><td>Standard_E16ads_v5</td><td>160</td><td>5</td><td>780</td></tr><tr><td>Standard_E16ads_v5</td><td>160</td><td>15</td><td>2,340</td></tr><tr><td>Standard_E16ads_v5</td><td>160</td><td>30</td><td>4,680</td></tr><tr><td>Standard_E16ads_v5</td><td>160</td><td>60</td><td>9,360</td></tr><tr><td>Standard_D32d_v4</td><td>320</td><td>5</td><td>1,580</td></tr><tr><td>Standard_D32d_v4</td><td>320</td><td>15</td><td>4,740</td></tr><tr><td>Standard_D32d_v4</td><td>320</td><td>30</td><td>9,480</td></tr><tr><td>Standard_D32d_v4</td><td>320</td><td>60</td><td>18,960</td></tr></tbody></table>

### Cluster size costs

The table shows the estimated monthly cost for various cluster sizes.

{% hint style="info" %}
The estimated monthly and annual costs do not include additional storage costs. To determine the additional storage costs, use [Microsoft Azure pricing calculator](https://azure.microsoft.com/en-us/pricing/calculator/) in the Microsoft documentation.&#x20;
{% endhint %}

<table><thead><tr><th width="194.69921875">Cluster size</th><th width="158.38671875">Number of cores</th><th>Estimated monthly cost</th><th>Estimated annual cost</th></tr></thead><tbody><tr><td>Standard_E2ads_v5</td><td>2</td><td>$512 </td><td>$6,144</td></tr><tr><td>Standard_E4ads_v5</td><td>4</td><td>$1,024 </td><td>$12,288</td></tr><tr><td>Standard_E8ads_v5</td><td>8</td><td>$2,050 </td><td>$24,600</td></tr><tr><td>Standard_E16ads_v5</td><td>16</td><td>$4,099 </td><td>$49,188</td></tr><tr><td>Standard_D32d_v4</td><td>32</td><td>$7,781 </td><td>$93,372</td></tr></tbody></table>


# Log Analytics Cross-Tenant Search

Learn how to configure Azure Lighthouse to enable cross-tenant searches in Microsoft Log Analytics.

In order to execute cross-tenant queries against a Microsoft Azure Log Analytics Workspace, the proper permissions first need to be configured. This can be done using [Azure Lighthouse](https://azure.microsoft.com/en-us/products/azure-lighthouse#layout-container-uidf657), a **free** service that assists customers in managing multiple Azure tenants. In this case, it is used to assign role-based access control (RBAC) permissions to grant service principals permissions across tenants.&#x20;

What follows are the instructions to set up Azure Lighthouse to enable the Anvilogic Azure integration to query across Log Analytics Workspaces in different Azure tenants.

## Terminology

* <mark style="background-color:red;">**Provider**</mark> - The tenant that is providing the service (in which the Anvilogic ADX cluster was deployed).
* <mark style="background-color:green;">**Customer**</mark> - The tenant that the provider needs access to. This contains the Log Analytics Workspaces that will be searched.

There is only one provider, but there can be many customers.

## Other Considerations

At the moment, Microsoft does not support resource-level permissions. Their guidance is to place active DENY permissions for the Anvilogic service principal on any resources in the <mark style="background-color:green;">**Customer**</mark> Resource Group that you don't want it to be able to access.

Alternatively, you can move the Log Analytics Workspace to it's own resource group using the [Azure Resource Mover](https://learn.microsoft.com/en-us/azure/azure-resource-manager/management/move-resource-group-and-subscription?tabs=azure-cli). This is a non-destructive change and would not impact the workspace (i.e. it can be done while in production).

Microsoft also recommends that customers have only one Log Analytics Workspace per region. If customers are using multiple, that is an anti-pattern from Microsoft's perspective. For more information, see <https://learn.microsoft.com/en-us/azure/azure-monitor/logs/workspace-design>.


# Anvilogic on Snowflake Architecture

Anvilogic implementation on Snowflake (AWS, GCP, Azure).

### Architecture Diagram&#x20;

Below is the generic architecture digram for how Anvilogic works on top of Snowflake. &#x20;

{% hint style="info" %}
This supports Snowflake on Azure, AWS, and GCP.
{% endhint %}

**Overall Diagram:**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FfNXb54ekPh4D2mx5wfJC%2FScreenshot%202024-07-09%20at%2012.20.52%20PM.png?alt=media&amp;token=8f1393af-ff3b-450a-97f7-b023526de1e5" alt=""><figcaption><p>Anvilogic on Snowflake (AWS, GCP, or Azure)</p></figcaption></figure>

**ETL Parsing & Normalization Process**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FZiVE1dHyM9t7J5PfWgZE%2FETL%20Process%20Snowflake%20(10).png?alt=media&amp;token=d015c912-72f7-4f62-a2b7-401e61ad8f60" alt=""><figcaption><p>ETL Process for moving data from Raw format to Gold.</p></figcaption></figure>

**PDF Download:**

{% file src="/files/klbSurBGYJ190tYc1WQl" %}

### Frequently Asked Questions (FAQs)

<details>

<summary>Does it matter which public cloud I own?</summary>

Snowflake will be configured in the IaaS environment that you have and is available across AWS, GCP, and Azure.

You can also have a separate Snowflake account per environment if you are a multi-IaaS organization.

Data that already originates in IaaS that can be sent to cloud storage does not require a streaming tool and can be onboarded to Snowflake directly.

</details>

<details>

<summary>How do I onboard logs from data center assets?</summary>

Datasets that come from assets hosted within a data center or not in a public IaaS environment will require a solution to route that data to Snowflake.

Data streaming tools (ex. Cribl, Fluentbit, Apache NiFi) can be used to send on-prem. logs directly to Snowflake.

**It is a requirement that you have a data transport/streaming tool to send data to IaaS storage or Anvilogic pipelines for ingestion.**

Forwarding agents that are installed on endpoints also need to be re-configured to send to the streaming tools for ingestion into Snowflake.

**Snowflake and/or Anvilogic does not provide any data streaming or endpoint agent technology.**

</details>

<details>

<summary>How do you get data that originates in public cloud into Snowflake?</summary>

Configure your security tools & appliances to log to cloud storage services like S3, Blob storage, or GCP storage - Snowpipe then picks it up and ingests into Snowflake.

</details>

<details>

<summary>How does the Anvilogic SaaS platform communicate with the Snowflake database that gets installed in your Snowflake account?</summary>

All communication (search and detection use cases deployments) are done over REST API using HTTPS/443 with TLS v1.2+.

</details>

<details>

<summary>Can Anvilogic help with getting raw data into Snowflake?</summary>

**Yes**, if you have a streaming tool (ex. Cribl, [Fluentbit](/get-started/reference-architectures/anvilogic-on-snowflake-architecture/fluentbit), Apache NiFi) you can send custom data sources directly to Anvilogic’s ingestion pipeline. Anvilogic also has some out of the box support for raw data ingestion sources in our integrations armory.

This will send data to our S3 storage service, which temporarily stores data to process it into Snowflake.

</details>

<details>

<summary>Does Anvilogic help with parsing and normalization of raw data into Snowflake?</summary>

**Yes**, Anvilogic helps with all of the parsing and normalization of security relevant data into the Anvilogic schema.  We have onboarding templates and configs that will help ensure the data you are brining into Snowflake is properly formatted to execute detections and perform triage, hunting, and response. &#x20;

</details>

<details>

<summary>Can Anvilogic help getting enrichment data into Snowflake?</summary>

**Yes**, if you have third party Intel or CMDB tools that are required to be used within detection enrichment, those can be called via REST API and transported into a Snowflake table.

Anvilogic detections can then leverage those enrichment tables to enrich detections before those detections are stored in the Alert lake (upstream of SOAR).

</details>

<details>

<summary>Does Anvilogic have out-of-the-box integrations for specific vendors alert sources?</summary>

**Yes**, Anvilogic can provide out of the box integrations for common vendor alerts and data collection for specific SaaS Security tools (ex. Crowdstrike FDR).

Tools not listed in our integration marketplace can be sent through the Custom Data Integration pipeline as a self service option.

</details>

<details>

<summary>What is the difference between raw data vs Alert data?</summary>

Raw data sources are events/telemetry that is generated from endpoints/tools/appliances (ex. Windows Event logs, EDR logs).

Alerts data is curated signals from security tools (ex. Proofpoint alerts, Anti-virus alerts, etc.) that has already been identified to be suspicious or malicious by the vendor.

</details>

<details>

<summary>Do you use Snowflake Warehouses?</summary>

**Yes**, Anvilogic requires 2 warehouses to run.

* **Ad-hoc Warehouse -** Compute for queries to assist search, hunt, and IR
* **Detect Warehouse -** Run 24/7 executing scheduled tasks (detections) on a cron

</details>

<details>

<summary>Do you integrate with SOAR?</summary>

**Yes**, Anvilogic can integrate with most SOARs via REST API through either a push or a pull method.

</details>

<details>

<summary>Does Anvilogic have a search user interface (UI) for Snowflake?</summary>

**Yes**, Anvilogic has a search user interface (UI) to make it easy to query data that is inside of a Snowflake database. &#x20;

In addition, Anvilogic makes it easy to build repeatable detections that can execute on top of Snowflake using a low-code UI builder. &#x20;

</details>

<details>

<summary>Does Anvilogic have a data model?  Does it work with OCSF?</summary>

**Yes**, Anvilogic has a data model and offers parsing and normalization code for any security data set that you want to use within the platform.

Yes, we can also work with OCSF data, and each data feed can be modified/controlled to customize to your needs.

</details>

<details>

<summary>Does Anvilogic support IOC collection &#x26; searching?</summary>

**Yes**, Anvilogic can onboard IOCs from your third party threat intel tools (ex. Threat Connect) and use that data to create new detections, conduct ongoing exposure checks across your data feeds, or use it to enrich your alert output for triage analysts.

</details>


# FluentBit

The following page will help you understand how you can use FluentBit to send data to Anvilogic to ingest into Snowflake.

**What is FluentBit?**

Fluentd is an open source streaming tool that can be used to send data to Snowflake to leverage with Anvilogic.

{% embed url="<https://fluentbit.io/how-it-works/>" %}

{% hint style="info" %}
You can leverage the below configs as templates for how to stream common security data sets to Anvilogic's data onboarding pipeline. &#x20;

**Remember**: Anvilogic helps to parse and normalize this data to our schemas automatically once the data has been sent to our pipeline.
{% endhint %}

**Data Type Examples:**

{% content-ref url="/pages/tHkLh7w08YAbSXWbA0qR" %}
[Linux data](/get-started/reference-architectures/anvilogic-on-snowflake-architecture/fluentbit/linux-data)
{% endcontent-ref %}

{% content-ref url="/pages/5lMtNuV9OBXfe8tD1a6B" %}
[Syslog data](/get-started/reference-architectures/anvilogic-on-snowflake-architecture/fluentbit/syslog-data)
{% endcontent-ref %}

{% content-ref url="/pages/aJdPNa7R6dVjxrCpXgB3" %}
[Windows data](/get-started/reference-architectures/anvilogic-on-snowflake-architecture/fluentbit/windows-data)
{% endcontent-ref %}


# Linux data

This page is designed to help customers leverage the Forward Events integration within their Anvilogic account for FluentBit.

### Pre-Reqs

* Anvilogic account
* Snowflake data repository connected to your Anvilogic account
* [FluentBit installed](https://docs.fluentbit.io/manual/installation/getting-started-with-fluent-bit)

### Setting up FluentBit Config

1. Anvilogic will provide a S3 bucket and the corresponding access keys/ids (note these change for each integration) when you create a forward events integration in your Anvilogic deployment.
   1\.

   ```
   <figure><img src="/files/KKa0hTwAxkf5wEek0kVB" alt=""><figcaption></figcaption></figure>
   ```
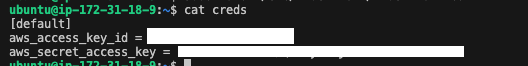
2. Create a credential file on the machine that fluentBit can read from. For example, `/home/<username>/creds` . Inside the file please paste the following config with your specific access key/id

```
[default]
aws_access_key_id = AKIAIOSFODNN7EXAMPLE
aws_secret_access_key = wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY
```

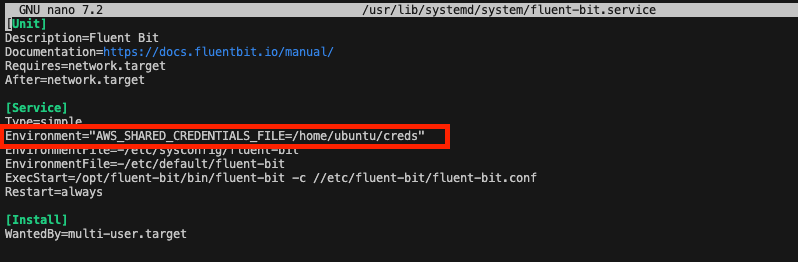
<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FX79vB1tREds6gCkZaXgx%2FScreenshot%202024-09-09%20at%2011.07.50%E2%80%AFAM.png?alt=media&amp;token=0ab7336e-af5c-4801-9868-b16be303cb0f" alt=""><figcaption></figcaption></figure>

3. Since our credentials are already updated in the `/home/<username>/creds` file, we need to configure the service config file for Fluent Bit and set the path to this credential file (see image for reference). To do that, fire up your favorite text editor and edit the fluent-bit.service file located at /usr/lib/systemd/system/fluent-bit.service.
   1. `Environment="AWS_SHARED_CREDENTIALS_FILE=/home/<username>/creds"`

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FDyvkw01tE9UFJybIvyE4%2FScreenshot%202024-09-09%20at%2011.08.59%E2%80%AFAM.png?alt=media&amp;token=881f3980-8c2e-4188-934f-e41739c45e3f" alt=""><figcaption></figcaption></figure>

4. Then run the following commands in a terminal window
   1. `sudo systemctl daemon-reload`
   2. &#x20;`sudo systemctl start fluent-bit`
5. Next we need to configure fluentbit to read our logs and send them to S3. In this example, I will be looking at apache2 access logs and sending them to S3.

```
[INPUT]
    Name              tail
    Tag               apache
    Path              /var/log/apache2/access.log
    Parser            apache2
    Mem_Buf_Limit     50MB

[OUTPUT]
    Name              s3
    Match             *
    bucket            avl-raw-prod-s3-111-12345678/sdi_custom_data-0
    region            us-east-1
    use_put_object    On
    Store_dir         /tmp/fluent-bit/s3
    s3_key_format     /$TAG/%Y/%m/%d/%H/%M/%S
```

Once you have pasted the above config into your fluentBit.conf file (typically located at /etc/fluent-bit/fluent-bit.conf)

* **NOTE**: You can also edit or add any of your own customer parsers for logs by editing the parser.conf file at /etc/fluent-bit/
* Once you have edited your fluent-bit.conf, please restart the fluentBit service `sudo systemctl restart fluent-bit`
  * You can validate that your config is working by heading to /tmp/fluent-bit/s3/ and looking inside that folder.

6. You can now confirm that data has landed in your snowflake account.&#x20;
   1\.

   ```
   <figure><img src="/files/HK3yNIdRyiOmujnN83U0" alt=""><figcaption></figcaption></figure>

   <figure><img src="/files/wPqH4RlxXgT2qby6jc3d" alt=""><figcaption></figcaption></figure>
   ```

Please update the input section of this example config to fit your exact needs.


# Syslog data

This page is designed to help customers leverage the Forward Events integration within their Anvilogic account for FluentBit.

### Pre-Reqs

* Anvilogic account
* Snowflake data repository connected to your Anvilogic account
* [FluentBit installed](https://docs.fluentbit.io/manual/installation/getting-started-with-fluent-bit)

### Setting up FluentBit Config

1. Anvilogic will provide a S3 bucket and the corresponding access keys/ids (note these change for each integration) when you create a forward events integration in your Anvilogic deployment.
   1\.

   ```
   <figure><img src="/files/KKa0hTwAxkf5wEek0kVB" alt=""><figcaption></figcaption></figure>
   ```
2. Create a credential file on the machine that fluentBit can read from. For example, `/home/<username>/creds` . Inside the file please paste the following config with your specific access key/id

```
[default]
aws_access_key_id = AKIAIOSFODNN7EXAMPLE
aws_secret_access_key = wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY
```

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FX79vB1tREds6gCkZaXgx%2FScreenshot%202024-09-09%20at%2011.07.50%E2%80%AFAM.png?alt=media&amp;token=0ab7336e-af5c-4801-9868-b16be303cb0f" alt=""><figcaption></figcaption></figure>

3. Since our credentials are already updated in the `/home/<username>/creds` file, we need to configure the service config file for Fluent Bit and set the path to this credential file (see image for reference). To do that, fire up your favorite text editor and edit the fluent-bit.service file located at /usr/lib/systemd/system/fluent-bit.service.
   1. `Environment="AWS_SHARED_CREDENTIALS_FILE=/home/<username>/creds"`

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FDyvkw01tE9UFJybIvyE4%2FScreenshot%202024-09-09%20at%2011.08.59%E2%80%AFAM.png?alt=media&amp;token=881f3980-8c2e-4188-934f-e41739c45e3f" alt=""><figcaption></figcaption></figure>

4. Then run the following commands in a terminal window
   1. `sudo systemctl daemon-reload`
   2. &#x20;`sudo systemctl start fluent-bit`
5. Next we need to configure fluentbit to read our logs and send them to S3. In this example, I will be sending logs via Syslog and sending them to S3.

```
[INPUT]
    Name              syslog
    Mode              udp
    Listen            0.0.0.0
    Port              1515
    Parser            syslog-rfc3164
    Mem_Buf_Limit     10MB

[OUTPUT]
    Name              s3
    Match             *
    bucket            avl-raw-prod-s3-221-24243202/sdi_custom_data-0
    region            us-east-1
    use_put_object    On
    Store_dir         /tmp/fluent-bit/s3
    s3_key_format     /$TAG/%Y/%m/%d/%H/%M/%S
```

Once you have pasted the above config into your fluentBit.conf file (typically located at /etc/fluent-bit/fluent-bit.conf)

* **NOTE**: You can also edit or add any of your own customer parsers for logs by editing the parser.conf file at /etc/fluent-bit/
* Once you have edited your fluent-bit.conf, please restart the fluentBit service `sudo systemctl restart fluent-bit`
  * You can validate that your config is working by heading to /tmp/fluent-bit/s3/ and looking inside that folder.

6. You can now confirm that data has landed in your snowflake account.&#x20;
   1\.

   ```
   <figure><img src="/files/RFKLavrNnA2rRY5bxnVs" alt=""><figcaption></figcaption></figure>

   <figure><img src="/files/AHn6sAUjAX3cuiFInUvC" alt=""><figcaption></figcaption></figure>
   ```

Please update the input section of this example config to fit your exact needs.


# Windows data

This page is designed to help customers leverage the Forward Events integration within their Anvilogic account for FluentBit.

### Pre-Reqs

* Anvilogic account
* Snowflake data repository connected to your Anvilogic account
* [AWS CLI Installed ](https://docs.aws.amazon.com/cli/latest/userguide/getting-started-install.html)
* [FluentBit installed](https://docs.fluentbit.io/manual/installation/getting-started-with-fluent-bit)

### Setting up FluentBit Config

1. Anvilogic will provide a S3 bucket and the corresponding access keys/ids (note these change for each integration) when you create a forward events integration in your Anvilogic deployment.
   1\.

   ```
   <figure><img src="/files/KKa0hTwAxkf5wEek0kVB" alt=""><figcaption></figcaption></figure>
   ```
2. Following the steps of the AWS CLI install, once you have done the installation correctly - Please run `aws configure` and paste in the access key and id provided. Once this is completed, validate that the credentials have been created - usually `C:\Users\YourUsername.aws\credentials`.
3. Once that has been validated, we need to create a system variable in order for fluentBit to read/use these credentials. To do so;
   1. Open the Start Menu and search for “Environment Variables.”
   2. Select Edit the system environment variables.
   3. In the System Properties window, click the Environment Variables button.
   4. Under System variables, click New.
   5. Enter the following:
      1. Variable name: AWS\_SHARED\_CREDENTIALS\_FILE
      2. Variable value: C:\Users\YourUsername\\.aws\credentials
   6. Next we need to configure fluentbit to read our logs and send them to S3. In this example, we will be ingesting the windows event logs. You can change what channels by simply adding or removing them.&#x20;
      1. Please note, the bucket will be the bucket name/path.&#x20;
         1. This could mean that it is sdi\_customer\_data-1 or -2 or -3.&#x20;

```
[INPUT]
    Name         winlog
    Channels     Security, Application, System
    Interval_Sec 1

[OUTPUT]
    Name              s3
    Match             *
    bucket            avl-raw-prod-s3-221-24243202/sdi_custom_data-1
    region            us-east-1
    use_put_object    On
    Store_dir         C:\Windows\Temp\fluent-bit\s3
    s3_key_format     /$TAG/%Y/%m/%d/%H-%M-%S
```

Once you have pasted the above config into your fluentBit.conf file (typically located at C:\Program Files\fluent-bit\conf )

* **NOTE**: You can also edit or add any of your own customer parsers for logs by editing the parser.conf file at /etc/fluent-bit/
* Once you have edited your fluent-bit.conf, please restart the fluentBit application

5. You can now confirm that data has landed in your snowflake account.&#x20;
   1\.

   ```
   <figure><img src="/files/qKLIibse9zSW6Ng9K5c6" alt=""><figcaption></figcaption></figure>

   <figure><img src="/files/SF6TwCeyypJEDUuLTtlK" alt=""><figcaption></figcaption></figure>
   ```

Please update the input section of this example config to fit your exact needs.&#x20;


# Fluentd

The following page will help you understand how you can use Fluentd to send data to Anvilogic to ingest into Snowflake.

**What is Fluentd?**

Fluentd is an open source streaming tool that can be used to send data to Snowflake to leverage with Anvilogic.&#x20;

{% embed url="<https://www.fluentd.org/architecture>" %}

{% hint style="info" %}
You can leverage the below configs as templates for how to stream common security data sets to Anvilogic's data onboarding pipeline. &#x20;

**Remember**: Anvilogic helps to parse and normalize this data to our schemas automatically once the data has been sent to our pipeline.
{% endhint %}

{% embed url="<https://docs.fluentd.org/>" %}


# Anvilogic on Databricks Architecture

Anvilogic implementation on Databricks (AWS, Azure, GCP).

<div align="left"><figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FnBbxQoIgAjPpnFdWeHe3%2Fdatabricks-partner-badges.png?alt=media&amp;token=89952445-75b4-4523-9452-6764fe5ee335" alt="Databricks Technology Partner and Built-On Partner Badges"><figcaption></figcaption></figure></div>

### Architecture Diagram&#x20;

Below is the generic architecture digram for how Anvilogic works on top of Databricks. &#x20;

{% hint style="info" %}
This supports Databricks on AWS, Azure, and GCP.
{% endhint %}

**Diagram:**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FrZhcI02SIVhydn7NN0YG%2FDatabricks-Reference-Architecture.jpg?alt=media&amp;token=b8f53f0c-2376-4202-a80f-004493c1392d" alt="Reference architecture diagram for Anvilogic on Databricks"><figcaption><p>Anvilogic on Databricks (AWS, GCP, or Azure)</p></figcaption></figure>

**ETL Parsing & Normalization Process**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FoCtUEYwrSf9Vxpq76laa%2FETL-Process-Databricks.jpg?alt=media&amp;token=46f85c67-d3c0-4ca2-8505-d323afe8245d" alt=""><figcaption><p>ETL Process for moving data from Raw format to Gold.</p></figcaption></figure>

**PDF Download:**

{% file src="/files/pk7SdoTnY7trx1iqMnq7" %}

### Frequently Asked Questions (FAQs)

<details>

<summary>Does it matter which public cloud I own?</summary>

Databricks will be configured in the IaaS environment that you have and is available across AWS, Azure, and GCP.

Data that already originates in IaaS that can be sent to cloud storage does not require a streaming tool and can be onboarded to Databricks directly.

</details>

<details>

<summary>What type of Databricks Compute is required?</summary>

Anvilogic requires two types of compute warehouses to run:

1. [**SQL Warehouse**](https://docs.databricks.com/aws/en/compute/sql-warehouse) - Compute for ad-hoc queries to assist search, hunt, and IR
2. [**All-Purpose/Job Compute**](https://docs.databricks.com/aws/en/compute/use-compute) - Used to execute scheduled detection workflow jobs and for our low-code detection builder

For both, you have the option to use either **serverless** or **classic** compute, but serverless is the default and **highly recommended** for improved performance, scalability, and cost. &#x20;

</details>

<details>

<summary>How do detection use cases execute in Databricks?</summary>

Detections execute as jobs within a [Workflow](https://docs.databricks.com/en/jobs/index.html).  Rules built on the Anvilogic platform are converted from a user friendly SQL builder to PySpark functions that run on a defined schedule. &#x20;

</details>

<details>

<summary>How do I onboard logs from data center assets?</summary>

Datasets that come from assets hosted within a data center or not in a public IaaS environment will require a solution to route that data to Databricks.

Data streaming tools (ex. Cribl, Fluentbit, Apache NiFi) can be used to send on-prem. logs directly to Databricks.

**It is a requirement that you have a data transport/streaming tool to send data to IaaS storage or Anvilogic pipelines for ingestion.**

Forwarding agents that are installed on endpoints also need to be re-configured to send to the streaming tools for ingestion into Databricks.

**Databricks and/or Anvilogic does not provide any data streaming or endpoint agent technology.**

</details>

<details>

<summary>How do you get data that originates in public cloud into Databricks?</summary>

Python Notebooks are used to collect data from storage and transform raw events into the AVL detection schema, preferably using [Lakeflow Pipelines](https://docs.databricks.com/aws/en/ldp/) (formerly known as Delta Live Tables).

</details>

<details>

<summary>Can Anvilogic help with getting raw data into Databricks?</summary>

**Yes**, if you have a streaming tool (ex. Cribl, [Fluentbit](/get-started/reference-architectures/anvilogic-on-snowflake-architecture/fluentbit), Apache NiFi) you can send custom data sources directly to your primary storage servers (ex. S3, Blob, etc.) and Anvilogic can orchestrate the ETL process into the correct schema and tables required for detection purposes. &#x20;

</details>

<details>

<summary>Does Anvilogic help with parsing and normalization of raw data into Databricks?</summary>

**Yes**, Anvilogic helps with all of the parsing and normalization of security relevant data into the Anvilogic schema. &#x20;

We have onboarding templates and configs that will help ensure the data you are bringing into Databricks is properly formatted to execute detections and perform triage, hunting, and response. &#x20;

All data parsing, normalization, and enrichment is done in the Python Notebook section of the diagram above. &#x20;

</details>

<details>

<summary>What is the difference between Bronze, Silver, and Gold tables?</summary>

Anvilogic leverages Databricks Lakeflow Pipelines to assist in the ETL process of parsing, normalization and enrichment.

* **Bronze Tables** - Unparsed and unstructured data, usually in 2 columns (time and raw).&#x20;
* **Silver Tables** - Parsed and structured data; this is usually where raw data is separated into multiple columns (normalization and enrichment can also occur here).&#x20;
* **Gold Tables** - Normalized and enriched security data feeds that have been organized into tables based on their security domain (ex. Endpoint, Cloud, Network, etc).

Each feed can be customized based on your organization's preferences. &#x20;

</details>

<details>

<summary>Does Anvilogic have out-of-the-box integrations for specific vendors alert sources?</summary>

**Yes**, Anvilogic can provide out of the box integrations for common vendor alerts and data collection for specific SaaS Security tools (ex. Crowdstrike FDR).

Tools not listed in our integration marketplace can be sent through the Custom Data Integration pipeline as a self service option.

</details>

<details>

<summary>What is the difference between raw data and alert data?</summary>

Raw data sources are events/telemetry that is generated from endpoints/tools/appliances (ex. Windows Event logs, EDR logs).

Alerts data is curated signals from security tools (ex. Proofpoint alerts, Anti-virus alerts, etc.) that has already been identified to be suspicious or malicious by the vendor.

</details>

<details>

<summary>Do you integrate with SOAR?</summary>

**Yes**, Anvilogic can integrate with most SOARs via REST API through either a push or a pull method.

</details>

<details>

<summary>Does Anvilogic have a search user interface (UI) for Databricks?</summary>

**Yes**, Anvilogic has a search user interface (UI) to make it easy to query data that is inside of a Databricks catalog. &#x20;

In addition, Anvilogic makes it easy to build repeatable detections that can execute on top of Databricks using a low-code UI builder. &#x20;

</details>

<details>

<summary>Does Anvilogic have a data model?  Does it work with OCSF?</summary>

**Yes**, Anvilogic has a data model and offers parsing and normalization code for any security data set that you want to use within the platform.

Yes, we can also work with OCSF data, and each data feed can be modified/controlled to customize to your needs.

</details>

<details>

<summary>Does Anvilogic support IOC collection &#x26; searching?</summary>

**Yes**, Anvilogic can onboard IOCs from your third party threat intel tools (ex. Threat Connect) and use that data to create new detections, conduct ongoing exposure checks across your data feeds, or use it to enrich your alert output for triage analysts.

</details>


# Hybrid - Anvilogic on Splunk & Snowflake Architecture

Anvilogic implementation with Splunk & Snowflake.

### Architecture Diagram&#x20;

Below is the generic architecture digram for how Anvilogic works on top of a hybrid data environment like Snowflake & Splunk

{% hint style="info" %}

* This supports **Snowflake** on Azure, AWS, and GCP.
* This supports **Splunk** on Splunk Cloud, Splunk Enterprise on-premise, and Splunk Enterprise Security (ES)
  {% endhint %}

**Diagram:**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FeyabgakJuB4RFgLoxScC%2FReference%20Architecture%20-%20Hybrid%20Splunk%20%26%20Snowflake.png?alt=media&amp;token=175e4703-d186-4c74-83ed-e7b98116ddb0" alt=""><figcaption><p>Anvilogic on Snowflake (AWS, GCP, or Azure) and Splunk (Cloud or On-Premise)</p></figcaption></figure>

**PDF Download:**

{% file src="/files/ePyisFVE2jYO0F2N8ica" %}

**Hybrid FAQ**

<details>

<summary>What is the EOI routing pipeline?</summary>

With a multi platform SIEM, you need to select a primary location to store all of your Alerts, this in the Anvilogic platform is called your “Events of Interest (EOI)”.

You will select which logging platform you want to contain your consolidated EOIs from all detection inputs and the EOI routing pipeline will ensure all alerts (regardless where they original from) get routed to land in the correct destination for correlation opportunities across your data repositories.

**In this example Splunk was selected to be the primary EOI data repo**, which means all Snowflake alerts get routed to the Splunk index. If Snowflake was selected, then all Splunk alerts would get routed to the Snowflake alert table.

Anvilogic will also store a copy of all alerts generated in the platform Alert Lake, which is used for AI-Insights (ex. Tuning, Health, and Hunting escalations).

</details>

### Frequently Asked Questions (FAQs)

* [Splunk FAQ](/get-started/reference-architectures/anvilogic-on-splunk-architecture#frequently-asked-questions-faqs)
* [Snowflake FAQ](/get-started/reference-architectures/anvilogic-on-snowflake-architecture#frequently-asked-questions-faqs)


# Hybrid - Anvilogic on Splunk & Azure Architecture

Anvilogic implementation with Splunk & Snowflake.

Below is the generic architecture digram for how Anvilogic works on top of a hybrid data environment like Snowflake & Splunk

{% hint style="info" %}

* This supports **Azure** on Data Explorer, Log Analytics, Fabric, and Sentinel.
* This supports **Splunk** on Splunk Cloud, Splunk Enterprise on-premise, and Splunk Enterprise Security (ES)
  {% endhint %}

**Diagram:**

<figure><img src="https://4253518893-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyHwthHcpZXpcJV1cs4SA%2Fuploads%2FRgc13WMJsIMcjH1FDzHg%2FAnvilogic_Azure_Splunk_Hybrid.png?alt=media&amp;token=973ecc45-7637-4b1d-a11b-715e570c1a53" alt=""><figcaption><p>Anvilogic on Azure (Data Explorer, Log Analytics, Fabric, Sentinel) &#x26; Splunk (Cloud or On-Premise) Hybrid</p></figcaption></figure>

**PDF Download:**

{% file src="/files/Qx8Ey4YUVSccNzedNoIK" %}

**Hybrid FAQ**

<details>

<summary>What is the EOI routing pipeline?</summary>

With a multi platform SIEM, you need to select a primary location to store all of your Alerts, this in the Anvilogic platform is called your “Events of Interest (EOI)”.

You will select which logging platform you want to contain your consolidated EOIs from all detection inputs and the EOI routing pipeline will ensure all alerts (regardless where they original from) get routed to land in the correct destination for correlation opportunities across your data repositories.

**In this example Splunk was selected to be the primary EOI data repo**, which means all Snowflake alerts get routed to the Splunk index. If Snowflake was selected, then all Splunk alerts would get routed to the Snowflake alert table.

Anvilogic will also store a copy of all alerts generated in the platform Alert Lake, which is used for AI-Insights (ex. Tuning, Health, and Hunting escalations).

</details>

### Frequently Asked Questions (FAQs)

* [Splunk FAQ](/get-started/reference-architectures/anvilogic-on-splunk-architecture#frequently-asked-questions-faqs)
* [Azure FAQ](/get-started/reference-architectures/anvilogic-on-azure)


# AI Operating System Pricing

How Anvilogic meters AI work with credits across Blueprints, the Triage Agent, AI Chat, and the Anvilogic MCP Server.

## Monitor and Control AI Credit Consumption

Anvilogic prices AI usage with a single metric: **credits**. Credits are one currency across every AI surface in the platform, so there are no separate quotas per feature and no surprise line items.

Credits meter the AI and agent work the platform performs for you. They do not meter the data you send. Onboarding a new log source does not raise your credit consumption, and neither does a spike in event volume.

### Benefits

* **Credit monitoring and budgets.** See consumption by product, by day, and by workflow. Set daily budgets and adjust them whenever your operations change.
* **Full transparency.** Every run writes a usage record showing credits consumed and credits remaining. Fixed-rate activities are published rates, so you know the cost before the run.
* **Scalable and security first.** Credits are shared across the platform, so your capacity moves to whatever your team is working on that week. Approval gates, RBAC, and per-product budgets govern what agents run and how much they spend.

### How you buy

* You purchase credits in **yearly packs**. A pack is sized by an average daily consumption rate, then multiplied across the year.
* Inside the pack, you set **daily budgets** per product. Budgets are adjustable at any time, so a heavy detection engineering week or an incident surge does not require a new purchase.

#### Example credit packs

| Credits per day | Credits per year |
| --------------- | ---------------- |
| 300             | 109,500          |

Additional pack sizes are available. Your Anvilogic account team will size a pack against your alert volume and automation plans.

### How to calculate what you need

Start with alert volume. Triage is the largest and most predictable part of most teams' consumption, so it anchors the estimate.

1. **Count your average alerts per day.** Use a 30 day average, not a peak day.
2. **Double it.** The 2X pad covers the AI Chat sessions, Blueprint runs, and MCP tool calls that happen on top of triage.
3. **Round up to the nearest pack.**

#### Example

> **You average 150 alerts per day.**
>
> 150 alerts, doubled, is 300.
>
> **Start with the 300 credit per day pack. That is 109,500 credits for the year.**

That is the fastest way to get to a number. After 30 days of real usage, open the credit dashboard, compare actual daily consumption against the estimate, and adjust your daily budgets. If you plan to put Blueprints into production across several workflows in the first quarter, size above the 2X pad rather than at it.

### How credits are consumed

Two kinds of activity draw from the pack.

**Fixed rate.** A published credit cost per event. The cost does not vary with token count, tool calls, or run duration, so you know it in advance.

**Metered.** The cost scales with the work performed, because a Blueprint that onboards a data source and one that enriches an alert are not the same amount of work. Published averages give you a planning number, and budgets and per-run tracking apply to every metered activity.

<table><thead><tr><th width="149.109375">Product</th><th width="146.7109375">Activity</th><th width="120.09375">Type</th><th width="191.12890625">Description</th><th>Credits consumed</th></tr></thead><tbody><tr><td>Triage Agent</td><td>Threat Identifier verdict</td><td>Fixed rate</td><td>Verdict on a Threat Identifier alert.</td><td><strong>1 per alert</strong></td></tr><tr><td>Triage Agent</td><td>Threat Scenario verdict</td><td>Fixed rate</td><td>Verdict on a Threat Scenario alert.</td><td><strong>3 per alert</strong></td></tr><tr><td>Tuning Insight</td><td>Insight Accepted</td><td>Fixed rate</td><td>A tuning insight is accepted to tune a threat identifier - only counts for insights implemented - dismissed or ignored recommendations produce 0 credits</td><td><strong>1 per insight </strong><em><strong>accepted</strong></em></td></tr><tr><td>Hunting Insight</td><td>Insight Generated</td><td>Fixed rate</td><td>A hunting insight generated for suspicious activity </td><td><strong>3 per insight </strong><em><strong>generated</strong></em></td></tr><tr><td>Health Insight</td><td>Insight Generated</td><td>Fixed rate</td><td>Health insights generated for broken rules or pipelines - there are no credits used for health notifications</td><td><strong>0 credits per insight generated or accepted</strong></td></tr><tr><td>Anvilogic MCP Server</td><td>Tool call</td><td>Fixed rate</td><td>A single tool call executed through the Anvilogic MCP Server.</td><td><strong>1 credit per tool call</strong></td></tr><tr><td>Blueprints</td><td>Workflow run</td><td>Metered</td><td>Build and run your own agentic workflow across onboarding, detection, health, and investigation.</td><td>Averages <strong>20 credits per session</strong>*.</td></tr><tr><td>AI Chat</td><td>Ad-hoc chat interaction</td><td>Metered</td><td>Ad hoc chat interaction against your data, detections, and cases.</td><td>Averages <strong>2 credits per session</strong>*.</td></tr><tr><td>Federated Search</td><td>Ad-hoc chat interaction</td><td>Metered</td><td>Ad hoc search against your data and consolidate data sets.</td><td>Averages <strong>1 credits per session</strong>*.</td></tr></tbody></table>

Anvilogic may amend the rates in this table from time to time as reasonably required.

{% hint style="info" %}
**Metered\*** - for metered activity the above table represents the average credit consumption per session across existing Anvilogic customers.  This is not guaranteed for each session.
{% endhint %}

### Budgets and usage thresholds

You set budgets **per product, per day**, so consumption in one area cannot drain the pack for the rest. A runaway Blueprint does not take your Triage Agent offline.

* Set a daily budget for Blueprints, Triage Agent, AI Chat, and the Anvilogic MCP Server independently.
* Adjust any budget at any time. Budgets are guardrails, not fixed entitlements.
* Notifications fire as daily consumption approaches and crosses a budget, so your administrators act before work stops.
* Usage rolls up against the yearly pack. There is no monthly reset, so a busy day balances against a quiet one.

### Where to see your credits

Your credit dashboard lives at [**secure.anvilogic.com/settings/agents/credit\_dashboard**](https://secure.anvilogic.com/settings/agents/credit_dashboard), under Settings, Agents, Credit Dashboard.

The dashboard shows:

* Credits consumed against your yearly pack, with a breakdown by product.
* Day-by-day consumption, so peak periods and credit-heavy workflows are easy to spot.
* Per-run records showing credits consumed and credits remaining after each run.
* Consumption by workflow for Blueprints, so owners see which automations carry the cost.

### Best practices

* Check the credit dashboard weekly. Consumption patterns shift as new Blueprints go into production.
* Set daily budgets on Blueprints and AI Chat before rolling either out broadly. Both are metered, and both are where consumption grows fastest.
* Size your pack against alert volume first. Threat Identifier and Threat Scenario verdicts are fixed rate, so that part of your annual consumption is straightforward to forecast.
* Revisit your budgets after any change to detection content or alert routing that moves alert volume.


# AI security controls

This page summarizes the AI security controls and measures in place on the Anvilogic platform.

## Controls <a href="#map" id="map"></a>

The table summarizes the security controls in place for AI on the Anvilogic platform.

<table data-header-hidden data-full-width="true"><thead><tr><th width="269"></th><th></th></tr></thead><tbody><tr><td><strong>Control Category</strong></td><td><strong>Controls Applied</strong></td></tr><tr><td><strong>Context is established and understood.</strong></td><td><p>Intended purposes, potentially beneficial uses, context-specific laws, norms and expectations, and prospective settings in which the AI system will be deployed are understood and documented. Considerations include the specific set or types of users along with their expectations; potential positive and negative impacts of system uses to individuals, communities, organizations, society, and the planet; assumptions and related limitations about AI system purposes, uses, and risks across the development or product AI lifecycle; and related test, evaluation, verification, and validation (TEVV) and system metrics.</p><hr><p>The organization’s mission and relevant goals for AI technology are understood and documented. </p><hr><p>The business value or context of business use has been clearly defined or– in the case of assessing existing AI systems– re-evaluated. </p><hr><p>Organizational risk tolerances are determined and documented. </p><hr><p>System requirements (e.g., “the system shall respect the privacy of its users”) are elicited from and understood by relevant AI actors. Design decisions take socio-technical implications into account to address AI risks. </p></td></tr><tr><td><strong>Categorization of the AI system is performed.</strong></td><td><p>The specific tasks and methods used to implement the tasks that the AI system will support are defined (e.g., classifiers, generative models, recommenders). </p><hr><p>Scientific integrity and test, evaluation, verification, and validation (TEVV) considerations are identified and documented, including those related to experimental design, data collection and selection (e.g., availability, representativeness, suitability), system trustworthiness, and construct validation. </p></td></tr><tr><td><strong>AI capabilities, targeted usage, goals, and expected benefits and costs compared with appropriate benchmarks are understood.</strong></td><td><p>Potential benefits of intended AI system functionality and performance are examined and documented. </p><hr><p>Potential costs, including non-monetary costs, which result from expected or realized AI errors or system functionality and trustworthiness– as connected to organizational risk tolerance– are examined and documented. </p><hr><p>Targeted application scope is specified and documented based on the system’s capability, established context, and AI system categorization. </p><hr><p>Processes for operator and practitioner proficiency with AI system performance and trustworthiness– and relevant technical standards and certifications– are defined, assessed, and documented. </p><hr><p>Processes for human oversight are defined, assessed, and documented in accordance with organizational policies. </p></td></tr><tr><td><strong>Risks and benefits are mapped for all components of the AI system including third-party software and data.</strong></td><td>Internal risk controls for components of the AI system, including third-party AI technologies, are identified and documented. </td></tr><tr><td><strong>Impacts to individuals, groups, communities, organizations, and society are characterized.</strong></td><td><p>Likelihood and magnitude of each identified impact (both potentially beneficial and harmful) based on expected use, past uses of AI systems in similar contexts, public incident reports, feedback from those external to the team that developed or deployed the AI system, or other data are identified and documented. </p><hr><p>Practices and personnel for supporting regular engagement with relevant AI actors and integrating feedback about positive, negative, and unanticipated impacts are in place and documented. </p></td></tr><tr><td><strong>Manage deployment environment governance.</strong></td><td>When developing contracts for AI system products or services Consider deployment environment security requirements. </td></tr><tr><td><strong>Ensure a robust deployment environment architecture.</strong></td><td><p>Establish security protections for the boundaries between the IT environment and the AI system. </p><hr><p>Identify and protect all proprietary data sources the organization will use in AI model training or fine-tuning. Examine the list of data sources, when available, for models trained by others. </p></td></tr><tr><td><strong>Harden deployment environment configurations.</strong></td><td><p>Apply existing security best practices to the deployment environment. This includes sandboxing the environment running ML models within hardened containers or virtual machines (VMs), monitoring the network, configuring firewalls with allow lists, and other best practices for cloud deployments.</p><hr><p>Review hardware vendor guidance and notifications (e.g., for GPUs, CPUs, memory) and apply software patches and updates to minimize the risk of exploitation of vulnerabilities, preferably via the Common Security Advisory Framework (CSAF). </p><hr><p>Secure sensitive AI information (e.g., AI model weights, outputs, and logs) by encrypting the data at rest, and store encryption keys in a hardware security module (HSM) for later on-demand decryption. </p><hr><p>Implement strong authentication mechanisms, access controls, and secure communication protocols, such as by using the latest version of Transport Layer Security (TLS) to encrypt data in transit. </p><hr><p>Ensure the use of phishing-resistant multifactor authentication (MFA) for access to information and services. [2] Monitor for and respond to fraudulent authentication attempts. </p></td></tr><tr><td><strong>Protect deployment networks from threats.</strong></td><td><p>Use well-tested, high-performing cybersecurity solutions to identify attempts to gain unauthorized access efficiently and enhance the speed and accuracy of incident assessments. </p><hr><p>Integrate an incident detection system to help prioritize incidents. Also integrate a means to immediately block access by users suspected of being malicious or to disconnect all inbound connections to the AI models and systems in case of a major incident when a quick response is warranted. </p></td></tr><tr><td><strong>Continuously protect the AI system.</strong></td><td>Models are software, and, like all other software, may have vulnerabilities, other weaknesses, or malicious code or properties. Continuously monitor AI system. </td></tr><tr><td><strong>Validate the AI system before and during use.</strong></td><td>Store all forms of code (e.g., source code, executable code, infrastructure as code) and artifacts (e.g., models, parameters, configurations, data, tests) in a version control system with proper access controls to ensure only validated code is used and any changes are tracked. </td></tr><tr><td><strong>Secure exposed APIs.</strong></td><td>If the AI system exposes application programming interfaces (APIs), secure them by implementing authentication and authorization mechanisms for API access. Use secure protocols, such as HTTPS with encryption and authentication. </td></tr><tr><td><strong>Enforce strict access controls.</strong></td><td>Prevent unauthorized access or tampering with the AI model. Apply role-based access controls (RBAC), or preferably attribute-based access controls (ABAC) where feasible, to limit access to authorized personnel only. Distinguish between users and administrators. Require MFA and privileged access workstations (PAWs) for administrative access. </td></tr><tr><td><strong>Ensure user awareness and training.</strong></td><td>Educate users, administrators, and developers about security best practices, such as strong password management, phishing prevention, and secure data handling. Promote a security-aware culture to minimize the risk of human error. If possible, use a credential management system to limit, manage, and monitor credential use to minimize risks further. </td></tr><tr><td><strong>Conduct audits and penetration testing.</strong></td><td>Engage external security experts to conduct audits and penetration testing on ready to-deploy AI systems. </td></tr><tr><td><strong>Implement robust logging and monitoring.</strong></td><td>Establish alert systems to notify administrators of potential oracle-style adversarial compromise attempts, security breaches, or anomalies. Timely detection and response to cyber incidents are critical in safeguarding AI systems. </td></tr></tbody></table>

## Measure <a href="#measure" id="measure"></a>

The Measure function employs quantitative, qualitative, or mixed-method tools, techniques, and methodologies to analyze, assess, benchmark, and monitor AI risk and related impacts. It uses knowledge relevant to AI risks identified in the MAP function.

<table data-header-hidden data-full-width="true"><thead><tr><th width="271"></th><th></th></tr></thead><tbody><tr><td><strong>Measure</strong></td><td><strong>Measure Subcategories</strong></td></tr><tr><td><strong>MEASURE 1: Appropriate methods and metrics are identified and applied.</strong></td><td><p><strong>MEASURE 1.1:</strong> Approaches and metrics for measurement of AI risks enumerated during the MAP function are selected for implementation starting with the most significant AI risks. The risks or trustworthiness characteristics that will not– or cannot– be measured are properly documented.</p><hr><p><strong>MEASURE 1.2:</strong> Appropriateness of AI metrics and effectiveness of existing controls are regularly assessed and updated, including reports of errors and potential impacts on affected communities.</p><hr><p><strong>MEASURE 1.3:</strong> Internal experts who did not serve as front-line developers for the system and/or independent assessors are involved in regular assessments and updates. Domain experts, users, AI actors external to the team that developed or deployed the AI system, and affected communities are consulted in support of assessments as necessary per organizational risk tolerance.</p></td></tr><tr><td><strong>MEASURE 2: AI systems are evaluated for trustworthy characteristics.</strong></td><td><p><strong>MEASURE2.1:</strong> Test sets, metrics, and details about the tools used during test, evaluation, verification, and validation (TEVV) are documented.</p><hr><p><strong>MEASURE 2.2:</strong> Evaluations involving human subjects meet applicable requirements (including human subject protection) and are representative of the relevant population.</p><hr><p><strong>MEASURE 2.3:</strong> AI system performance or assurance criteria are measured qualitatively or quantitatively and demonstrated for conditions similar to deployment setting(s). Measures are documented.</p><hr><p><strong>MEASURE 2.4:</strong> The functionality and behavior of the AI system and its components– as identified in the MAP function– are monitored when in production.</p><hr><p><strong>MEASURE 2.5:</strong> The AI system to be deployed is demonstrated to be valid and reliable. Limitations of the generalizability be yond the conditions under which the technology was developed are documented.</p><hr><p><strong>MEASURE 2.6:</strong> The AI system is evaluated regularly for safety risks– as identified in the MAP function. The AI system to be deployed is demonstrated to be safe, its residual negative risk does not exceed the risk tolerance, and it can fail safely, particularly if made to operate beyond its knowledge limits. Safety metrics reflect system reliability and robustness, real-time monitoring, and response times for AI system failures.</p><hr><p><strong>MEASURE 2.7:</strong> AI system security and resilience– as identified in the MAP function– are evaluated and documented.</p><hr><p><strong>MEASURE 2.8:</strong> Risks associated with transparency and account ability– as identified in the MAP function– are examined and documented.</p><hr><p><strong>MEASURE 2.9:</strong> The AI model is explained, validated, and documented, and AI system output is interpreted within its context as identified in the MAP function– to inform responsible use and governance.</p><hr><p><strong>MEASURE 2.10:</strong> Privacy risk of the AI system– as identified in the MAP function– is examined and documented.</p><hr><p><strong>MEASURE 2.11:</strong> Fairness and bias– as identified in the MAP function– are evaluated and results are documented.</p><hr><p><strong>MEASURE 2.12:</strong> Environmental impact and sustainability of AI model training and management activities– as identified in the MAP function– are assessed and documented.</p><hr><p><strong>MEASURE 2.13:</strong> Effectiveness of the employed test, evaluation, verification, and validation (TEVV) metrics and processes in the MEASURE function are evaluated and documented.</p></td></tr><tr><td><strong>MEASURE 3: Mechanisms for tracking identified AI risks over time are in place.</strong></td><td><p><strong>MEASURE 3.1:</strong> Approaches, personnel, and documentation are in place to regularly identify and track existing, unanticipated, and emergent AI risks based on factors such as intended and actual performance in deployed contexts.</p><hr><p><strong>MEASURE 3.2:</strong> Risk tracking approaches are considered for settings where AI risks are difficult to assess using currently available measurement techniques or where metrics are not yet available.</p><hr><p><strong>MEASURE 3.3:</strong> Feedback processes for end users and impacted communities to report problems and appeal system outcomes are established and integrated into AI system evaluation metrics.</p></td></tr><tr><td><strong>MEASURE 4: Feedback about efficacy of measurement is gathered and assessed.</strong></td><td><p><strong>MEASURE4.1:</strong> Measurement approaches for identifying AI risks are connected to deployment context(s) and informed through consultation with domain experts and other end users. Approaches are documented.</p><hr><p><strong>MEASURE 4.2:</strong> Measurement results regarding AI system trust worthiness in deployment context(s) and across the AI lifecycle are informed by input from domain experts and relevant AI ac tors to validate whether the system is performing consistently as intended. Results are documented.</p><hr><p><strong>MEASURE 4.3:</strong> Measurable performance improvements or declines based on consultations with relevant AI actors, including affected communities, and field data about context relevant risks and trustworthiness characteristics are identified and documented.</p></td></tr></tbody></table>


# AI Chat & AI privacy and controls

Frequently asked questions around privacy and security controls for AI Chat and AI used within the Anvilogic platform.

<details>

<summary>Is any customer data used to train the AI models in either AI Insights or Copilot?</summary>

Anvilogic agrees that it shall not use, process, or allow access to sensitive or raw Customer Data for the purpose of training, developing, or refining artificial intelligence (AI) models, or any other automated decision-making technologies.

</details>

<details>

<summary>Is any of the data in the conversations with Monte Copilot being used for model training?</summary>

No. Any data sent to Monte Copilot is not used to train the models. Customer feedback when using Monte Copilot in the form of a thumbs up/down will be used to tune the responses using prompt engineering.

</details>

<details>

<summary>Does Monte Copilot use a public or private model?</summary>

Monte Copilot uses OpenAI-hosted models.

</details>

<details>

<summary>Is PII, PHI and/or PCI data going to be used by Monte Copilot?</summary>

Though Monte Copilot may capture the PII data that was submitted by the users during a conversation, this PII data is removed and not processed via LLM Models.&#x20;

</details>

<details>

<summary>Do customers have the option to opt out of Monte Copilot?</summary>

Yes, all generative AI capabilities are part of add-ons. A customer has to purchase these add-ons to use the capabilities.&#x20;

</details>

<details>

<summary>Do you inventory all your AI models, and do you regularly reassess them for risk and compliance?</summary>

Weekly and Monthly output reviews are conducted on models. Models are stored in either UDFs or Sagemaker endpoints. Risks are identified during output reviews and remediated.

</details>

<details>

<summary>Do you prevent and/or identify and mitigate false positives, data loss prevention and unintended consequences of the AI's outputs?</summary>

We use regular expressions to mitigate clearly false positives, if there is a problem with the model, we generate a new model that addresses the perceived shortcomings.

</details>

<details>

<summary>Do you provide training and support to your employees who are using generative AI?</summary>

Due to the continuous evolution of AI, the team's training is a hands-on approach through weekly meetings to discuss our research and implementation of generative AI-based technologies. In these discussions, we cover the latest information about best practices and knowledge sharing regarding technology and software libraries related to generative AI.

</details>

<details>

<summary>What customer data, if any, does the solution require for training and/or maintenance?</summary>

None.

</details>

<details>

<summary>Does the Monte Copilot solution leverage protected attributes such as gender, race, age, disability, spoken language, mental health, or marital status, and proxy features of protected attributes, such as ZIP code?</summary>

No.

</details>

<details>

<summary>Are there roles to control which users can use Monte Copilot?</summary>

Not yet, but RBAC around what team members can use Monte Copilot will be implemented before our generally available (GA) release. &#x20;

</details>

<details>

<summary>Where does the data from questions and answers get stored?  For how long are Q&#x26;A stored?  Can Q&#x26;A be deleted?</summary>

Questions and answers are stored within an Anvilogic owned database hosted on Anvilogic's AWS instance. &#x20;

By default, Q\&A are stored for 30 days and then rolled off, unless feedback (thumbs down or thumbs up) were provided. &#x20;

This data can be deleted by an Anvilogic engineer with access if required. &#x20;

</details>